第 15 期 · 2026-W44 2026年10月25日 — 11月01日
✦ 本周速览

本周聚焦AI领域前沿,探讨数据管线构建与算力升级之道。最值得关注的是头条《JetBrains/thinkrail》,深入解析AI技术如何赋能产业升级。同时,不容错过的还有《超节点火了一年后,“算力不够就加机器”的扩张逻辑正在被改写》和《XHEART的炼芯术士》,带您领略AI技术带来的变革与机遇。

JetBrains/thinkrail 配图
头 条

JetBrains/thinkrail

核心内容
ThinkRail是一个智能IDE,它通过持续的学习和使用,不断提升自身能力。它能够通过活化的规格学习项目,并基于用户的工作方式构建自己的功能。
为什么重要
ThinkRail的重要性在于它代表了IDE的未来发展方向,即结合人工智能和自动化工具,以提高开发效率。它反映了对软件开发过程中自动化和智能化的追求,这可能对整个软件开发行业产生深远的影响。
关键洞察
最关键的观点是ThinkRail通过活化的规格和可重用的技能,赋予智能代理持久的项目知识。它还提供了隔离的工作空间、丰富的编辑器界面、实时更新的文件树和变更视图,以及能够流式传输的聊天功能,这些特性都旨在提高开发效率。
潜在影响
ThinkRail可能会影响软件开发者、团队和整个软件开发行业。开发者将受益于更高效的工作流程和更少的手动操作,团队可能会更快速地交付高质量的产品,而整个行业可能会因为这种自动化的IDE而加速创新和进步。

ThinkRail is the agentic IDE that gets better every time you use it — learning your project through living specs today, and building its own capabilities tomorrow. We built a rich interface around the pi coding agent, isolated work into separate workspaces, and gave the agent durable project knowledge through living specs and reusable skills. Next, we're adding full extension support, so ThinkRail can create the tools it needs based on how you actually work.

展开全文收起全文剩余 26 段 · 约 14 分钟

Website: thinkrail.ai · Blog: thinkrail.ai/blog

A pi session and the change it made, scoped to an isolated git-worktree workspace.

What you get

Isolated workspaces. Open any git repo as a project and cut workspaces from it as git worktrees, each with its own branch and working directory. Agents work in parallel without touching your checkout; merge the good branch, delete the rest. You can also attach existing worktrees or explicitly work in the project folder itself. Finished and dormant workspaces settle onto a per-project shelf on their own — when their pull request merges or closes, or after a quiet week — and come back the moment you work in them. The topbar shows where the active branch stands against origin and its pull request, with the next step one click away: publish, push, or open a PR described from the plan, the commits, your PR template, or an agent-written draft. Once a GitHub PR is open it shows the CI checks and review decision, and lets you mark it ready, hand failing checks or a diverged branch to the agent, merge it with the repository's last-used method, reopen it, or delete the remote branch.

A real IDE around the agent. A splittable workbench of Monaco editor tabs, a Files tree with live git change marks and a Changed view, terminals, and documents — all scoped to the active workspace. Leave anchored review comments on files and diffs and send them to a chat as structured context, or open the worktree in your installed IDE.

Chats that stream like the engine thinks. Several concurrent pi sessions per workspace, each with its own model and live token and cost readout. Steer a running turn or queue a follow-up, delegate to subagents, and work a shared plan the agent updates and you edit — each completed step can be committed and reviewed on its own.

Specs as ground truth. A connected graph of SPEC.md files lives beside the code; the agent reads, searches, and maintains it through dedicated spec_* tools, so intent survives the session. The read-only Specs tool renders the graph as a tree in the workbench.

Skills and workflows. Portable Agent Skills you already keep for other coding agents are read in place, and bundled workflows guide project setup, design brainstorming, and shipping a pull request — pushing the workspace branch and opening or updating its GitHub PR through your own gh.

Agent tools beyond the shell. Web research, and inline diagrams, option comparisons and file previews rendered right in the chat — when the agent proposes a UI change it shows a before/after mockup you can comment on like a diff. Settings → Extensions lists the ThinkRail extensions the agent gets and lets you switch each one off.

MCP servers. Connect the MCP servers in your pi mcp.json (or add them, and a few presets, from Settings): ThinkRail asks in the chat before calls the server does not mark read-only (or always allows the tools you trust in a project), keeps servers a repository defines off until you approve them, signs you in to OAuth servers from Settings, and shows each chat's servers next to its background commands and subagents.

Your providers, your credentials. Sign in with JetBrains AI or connect any provider through pi's own auth. ThinkRail has no accounts of its own.

Your pi setup. ThinkRail reads your existing pi configuration (~/.pi/agent). To use another one — say a personal ~/.pi/agent-personal — or to pass extra environment variables to the agent, terminals and MCP servers, set them in Settings → Environment; they apply on the next start. A variable you set when launching (PI_CODING_AGENT_DIR=… thinkrail) still wins.

Desktop app or browser. A native desktop app, or the thinkrail CLI that opens the same app in your browser. Both embed the same engine host; app state lives under ~/.thinkrail.

Your language. Settings → Language follows your system language or a language you pick; English and Simplified Chinese are built in. Add a language ThinkRail doesn't ship yet by dropping a translated en.json into ~/.thinkrail/locales — it applies as you save. Agent replies and tool output stay as the agent wrote them.

The project's spec graph as a tree, with the spec itself rendered alongside.

Install

ThinkRail ships in two additive forms: a native desktop installer and the self-contained thinkrail CLI. Both are published with SHA256SUMS on the releases page.

Desktop

Download the thinkrail-desktop-* asset for your platform:

macOS 14+ (Apple Silicon or Intel) — open the DMG for your architecture: thinkrail-desktop-darwin-arm64.dmg or thinkrail-desktop-darwin-x64.dmg.

Windows x64 — extract the complete setup ZIP, then run its setup executable in place, next to its payload.

Linux x64 / ARM64 — extract the setup tarball and run installer. Desktop builds need glibc 2.38+ with GTK 3, WebKitGTK 4.1, Ayatana AppIndicator 3, and librsvg 2 — Ubuntu 24.04 or newer:

``` sudo apt install libgtk-3-0 libwebkit2gtk-4.1-0 libayatana-appindicator3-1 librsvg2-2 ```

Packaged stable and nightly desktop builds check for updates in the background and offer them in Settings → Updates: Download → Preparing update → Install & Restart. Nothing is applied until you choose Install & Restart. ThinkRail then shows the installation's progress and log, closes, and reopens on the new version. After the restart it tells you whether the update installed. If it didn't, it explains why and offers to retry. The updater appears only when the package carries a valid HTTPS feed identity; installations that predate that identity need one manual installation first.

Command line

The installer downloads the right binary, verifies its SHA-256 checksum, and puts thinkrail on your PATH.

参考来源: GitHub Trending
AI
超节点火了一年后,“算力不够就加机器”的扩张逻辑正在被改写 配图

超节点火了一年后,“算力不够就加机器”的扩张逻辑正在被改写

核心内容
文章主要讲述了AI算力基础设施领域,尤其是超节点技术的新发展。文章指出,随着AI算力需求的增长,传统的“算力不够就加机器”的扩张逻辑正在被改写,超节点技术通过整合大量AI芯片成为高效统一的计算单元,成为AI算力基础设施的新焦点。
为什么重要
这个内容值得关注,因为它反映了AI算力基础设施领域的最新技术发展趋势,以及这些技术如何影响AI产业的发展。随着AI技术的广泛应用,对算力的需求不断增长,超节点技术的发展将直接影响AI应用的性能和效率,进而影响整个AI产业的发展。
关键洞察
文章的关键洞察在于,超节点技术通过紧耦合互联与软硬协同,将大量AI芯片整合为高效统一的计算单元,有效解决了大模型训练中的数据搬运、跨芯片同步与内存利用率低等关键瓶颈。此外,文章强调了NVLink/CXL等高带宽互连技术是实现低时延通信的基础,以及软硬协同设计对性能增益的重要性。
潜在影响
超节点技术的发展将影响AI基础设施工程师、大模型系统架构师、高性能计算平台开发者等专业人士的工作。随着超节点技术的普及和应用,这些专业人士将需要掌握新的技术和方法,以应对AI算力基础设施的新挑战。同时,这也可能推动AI算力基础设施的升级换代,提高AI应用的性能和效率。

李冬梅

2026-10-30

展开全文收起全文剩余 75 段 · 约 15 分钟

北京

本文字数:5386 字

阅读完需:约 18 分钟

AI摘要

超节点正成为AI算力基础设施新焦点,其核心是通过紧耦合互联与软硬协同,将数百至上千颗AI芯片整合为高效统一的计算单元。

超节点直面大模型训练中数据搬运、跨芯片同步与内存利用率低等关键瓶颈;NVLink/CXL等高带宽互连是实现低时延通信的基础;软硬协同设计决定实际性能增益是否匹配硬件规模扩张。

适合AI基础设施工程师、大模型系统架构师、高性能计算平台开发者阅读。

几十卡、数百卡、上千卡,AI 算力基础设施的规模竞赛,正在进入一个新的阶段。

过去,大模型厂商展示算力实力,最直观的方式是拥有多少张 GPU、建设了多大规模的计算集群。如今,随着超节点成为 AI 基础设施领域的热门方向,厂商展示实力的方式又多了一个:能够把多少颗 AI 芯片连接起来,让它们像一台计算机一样协同工作。

从英伟达的 GB200 NVL72,到华为的数百卡、千卡级超节点,再到各家国产厂商陆续推出的紧耦合计算系统,超节点的规模不断扩大。72 卡、384 卡、1024 卡,这些数字也越来越频繁地出现在产品发布和技术讨论中。

乍看之下,这似乎是过去算力竞赛的延续:以前比谁拥有的 GPU 更多,现在比谁能把更多 GPU 连接在一起。

但超节点真正试图解决的,恰恰是过去那种依靠增加机器数量扩充算力的方式所暴露的问题。

当模型规模越来越大,计算不再是唯一的瓶颈。芯片之间的数据交换、不同计算任务之间的同步,以及内存资源能否被高效使用,都开始影响最终的运行效率。增加更多芯片固然能够提高理论算力,但如果大量时间被消耗在数据搬运和等待上,硬件投入就未必能够转化为相应的性能收益。

超节点由此受到关注。它希望通过更高带宽、更低时延的互联,以及计算、内存和软件系统的协同设计,让更多芯片成为一个紧密协作的计算整体。

不过,一个值得追问的问题也随之出现:当超节点本来是为了提高计算效率而出现,为什么卡数又成为最受关注的竞争指标?连接的芯片越多,就一定意味着模型运行得越快吗?

从“堆机器”到“重构连接”,超节点为什么突然火了?

超节点并不是简单地把过去的多卡服务器做得更大,它在试图改变计算资源的组织方式。

传统 AI 集群通常以多卡服务器为基本单元。以常见的八卡服务器为例,服务器内部通过 NVLink 等高速互联技术实现 GPU 之间的数据交换;当模型或训练任务需要更多资源时,再将多台服务器通过 InfiniBand 或以太网连接起来。

这种架构具有很强的扩展能力,也支撑了过去几年的大模型训练。但问题在于,服务器内部和服务器之间的通信并不处于同一个性能层级。

当模型能够在一台服务器内部完成主要计算时,数据可以依靠相对高速的内部互联进行交换。一旦模型规模超过单台服务器的承载范围,就需要把计算和数据分布到更多服务器上,频繁跨越节点边界。

对于需要大量同步和数据交换的任务而言,这些边界会直接影响效率。GPU 一方面负责执行计算,另一方面还要等待其他芯片完成计算、传回数据,才能继续下一步工作。

这就意味着,计算集群拥有多少理论算力,与模型实际能够获得多少有效算力,并不是一回事。

2024 年 3 月,英伟达在 GTC 发布 Blackwell 平台及 GB200 NVL72,为这道难题提供了一个醒目的新解法。

GB200 NVL72 将 72 颗 Blackwell GPU 连接进同一个 NVLink 域,把紧耦合计算的范围从传统多卡服务器进一步扩大到整个机柜。

它的出现,改变了增加资源的组织方式。过去,模型超出一台服务器的承载范围,就要更多地依赖服务器间网络;如今,更多 GPU 可以进入同一个高速互联域,在更紧密的连接范围内协作。超节点希望减少的,正是模型跨越这些边界时产生的通信和数据搬运开销。

对于大模型,这种变化有直接吸引力:更多芯片参与计算,也提供更多显存资源;更快的互联则为模型并行、专家间数据交换等操作创造了更好的条件。能否将这些条件转化为性能,仍要依靠模型切分、算子和调度优化,但系统设计已经有了新的空间。

后来公开的模型研发实践,进一步解释了这种需求。

2025 年 5 月,DeepSeek 团队发表架构论文,披露其使用的 H800 系统中,按论文的有效带宽口径,节点内 NVLink 通信约为 160GB/s,跨节点 InfiniBand 通信约为 40GB/s,相差约四倍。为控制混合专家模型的通信成本,团队限制了每个 Token 所访问的专家跨越多少个节点,并利用更快的节点内连接转发数据。

这项实践说明,芯片怎样连接,已经会反过来影响模型怎样设计。

超节点之所以受到关注,正是因为行业需要把更多资源用起来,同时减少资源之间的协作负担。

厂商很快沿着这一方向推出产品。

华为、浪潮信息、阿里云……几乎各大厂商都在布局超节点。2025 年 4 月,华为云发布 CloudMatrix 384,并宣布已在芜湖数据中心规模上线,将超节点推向数百卡规模。2026 年 7 月,华为公开展示 1024 卡配置的 Atlas 950 SuperPoD,提供 256TB 全局统一内存编址空间。浪潮信息近期也发布了元脑 SD200 Ultra,以 128 芯本土 AI 芯片构建紧耦合系统,提供 8TB 统一编址显存,并围绕通信和模型算子进行优化,单机承载运行 2.8 万亿参数的 Kimi K3 大模型,Token 生成时延首次突破 5.85 毫秒,相当于单用户速度 170 Tokens/s。

不同产品的芯片能力、互联机制和部署形态并不相同,但它们共同推动了一种变化:AI 基础设施的竞争,从采购多少芯片,进一步走向如何组织芯片。

只是,超节点火起来之后,卡数又成为最醒目的数字。几十卡、数百卡、上千卡,高速互联域的规模不断扩大,发布会上最容易传播的,依然是“能连多少卡”。

超节点真正的较量是什么?

超节点火起来,是因为更多芯片需要更高效地协作。但如果把“高效协作”简化成“连接更多芯片”,很容易又回到过去的规模竞争。因为,支撑大参数量模型究竟能“跑多快”才是超节点更值得较量的能力。

以 Kimi K3 为例,作为全球最大开源模型,K3 拥有 2.8 万亿总参数、104B 激活参数,官方推荐 64 卡甚至更大规模的 AI 服务器才能装得下。可“装得下”并不意味着“跑得快”。有业内人士表示,一般未经优化的超节点运行 Kimi K3,初始性能可能仅在 10 tokens/s 左右。

这也暴露出超节点规模扩张背后的另一个问题:芯片多了,性能是否真的同步增长?

72 卡、384 卡、1024 卡,数字越大,越容易成为发布会的主角。但对于用户,一个更大的计算域也确实意味着更多资源,可以容纳更大的模型、更多中间数据,并为并行计算提供空间。问题是,这些资源要付出多少代价才能被用起来?新增一倍芯片,能否换来相应的性能提升?

所以,超节点真正需要解决的,并不是“还能连接多少芯片”,而是如何让更多芯片高效协同,把堆叠起来的算力真正变成全球前沿模型的推理速度。

当被问及 Scale-up 域是否越大越好时,浪潮信息首席 AI 战略官刘军给出了一个直接的回答:“规模不重要。核心是你的衡量标准是你要跑什么样的模型?你为这样的模型所匹配的计算架构是不是能让这个模型发挥出效果。”

这句话需要放在他的技术路线和产品定位下理解,但它提出了一个关键判断:超节点的价值,最终要回到具体模型的实际性能。

一个模型需要多少芯片,并不能只看参数量。权重采用什么精度、上下文有多长、同时承接多少请求,都会影响内存需求;采用怎样的并行策略、计算过程中需要交换多少数据,又会影响互联需求。对于混合专家模型,还要看专家如何分布、每个 Token 需要跨越哪些芯片。

能把模型放进一个计算域,只是选型的起点。放进去之后能否达到目标时延、支持所需并发,才决定这套配置是否合适。为了让单个请求更快,可能需要更多芯片共同处理;为了承接更多请求,也可能更适合把资源分成多个实例。两种需求,并不一定指向同样大的计算域。

如果模型在较小的域内已经能够高效运行,继续扩大单域,未必比增加服务实例更划算。反过来,如果模型的容量和通信需求已经超出较小系统的承载范围,更大的紧耦合域就可能是必要选择。不存在一个脱离模型和业务、普遍适用的“最佳卡数”。

规模扩大,还会把协作本身变成更复杂的工程。

刘军在采访中指出,规模大了,通信成本及问题的放大效应也会上升。如果数据和计算相隔过远,通信、调度的开销可能超过新增计算资源带来的收益。

高速互联可以降低这些开销,却不会让它们消失。即便资源已经统一寻址,访问远端显存也不意味着与访问本地显存具有相同成本。数据经过多少跳、链路是否拥塞、计算能否与通信重叠,仍然影响实际性能。统一地址空间让资源更容易被访问,软件还需要决定怎样访问才高效。

超节点越大,对拓扑和软件的要求也越高。 它需要证明的,不只是所有卡都能连接起来,还包括资源能否灵活分配。大任务需要整个域时,系统能否高效协同;小任务只需要一部分资源时,剩余资源能否服务其他业务?不同任务之间是否会相互干扰?如果只能用满配跑出好成绩,却难以经济地承接日常负载,规模优势就可能变成闲置成本。

因此,超节点是否好用,不能只看它能容纳多大的模型,更要看目标模型在其中能否达到预期的时延和吞吐。

可靠性是另一笔不能略过的账。

刘军特别提到,长程 Agent 任务可能持续数小时甚至数天,运行中断会带来更大的损失。但这并不意味着大超节点必然不可靠,也不意味着一次底层故障一定让任务从头开始。最终影响取决于故障能否被隔离、任务状态是否保存,以及服务能否重试、迁移和恢复。

对用户来说,更值得追问的是:一条链路或一颗芯片出问题,会影响多少资源?维护一部分设备时,其他业务能否继续运行?恢复需要多久,会丢失多少进度?这些问题决定了规模扩张的风险能否被控制,不能用一次短时间性能测试代替。

最后,规模还要落实到机房和预算上。更多芯片需要相应的供电、散热和互联设施,也带来软件适配与运维成本。采购价只是投入的一部分。如果为了获得有限的性能提升,需要大幅改造机房,或者增加长期维护负担,那么更大配置未必具有更好的回报。

“超节点,难在统一寻址”

超节点真正的吸引力,在于把原本分散的计算和存储资源组织成一个更紧密的协作整体。问题是,“像一台计算机一样工作”是一种目标描述,背后仍有大量架构差异。

刘军在采访中特别强调统一寻址。他认为,如果只是将模型拆成多个部分,分别放到不同服务器上运行,那仍然属于节点集群,浪潮信息所理解的超节点,需要首先解决显存统一寻址,让多颗加速器之间能够更直接地访问数据。

这是理解其技术路线的一个重要入口,但不能把它直接当成所有厂商共同遵循的定义。判断一套系统,仍需要拆开几个经常被混用的概念:资源是否具有统一的地址表达,远端访问能否由加速器直接发起,访问路径经过多少层交换,以及软件如何管理数据放置和同步。

统一寻址首先解决的是“能否找到、如何访问”的问题,并不自动意味着远端显存与本地显存具有相同的访问成本,也不自动保证所有资源都能高效共享。即便从软件看来,它们属于同一个地址空间,物理距离、拓扑和链路拥塞仍然存在。数据放在哪里、什么时候搬、能否与计算重叠,依然决定最终性能。

刘军用“串门”解释浪潮信息的对称内存方案:过去访问另一颗 GPU 的数据,像先去物业拿门条;现在则希望直接到邻居家。他强调,在统一寻址之后,还要进一步减少通信中的调度和中转开销。

这个比喻的价值,在于把超节点真正要解决的问题从“连接更多卡”拉回到“让这些卡更有效地协同”。如果扩大了资源池,却没有降低访问和同步成本,软件看到的空间可能更大,计算单元等待数据的时间也可能更长。

因此,“能放下模型”只是第一道门槛,“放下之后能否高效运行”才是更难的一道。

超节点如何选型:先看业务,再定规模

还有个问题值得关注,不同模型对系统的需求,并不随着参数量按同一种比例增长。

权重的存储需求与参数量、数据精度有关;推理时还要考虑上下文、并发请求及 KV Cache 等额外开销。对采用混合专家架构的模型而言,总参数量、每个 Token 实际激活的参数量,以及专家之间的通信,也分别约束着容量、计算和互联。仅凭“支持多少万亿参数”,很难推导真实的服务能力。

训练和推理的规模选择同样不能混为一谈。训练通常更关注一次训练任务的扩展效率;推理还要同时兼顾首 Token 时延、后续 Token 生成速度、并发和总吞吐。在一个大域内让单个请求更快,与将资源拆成多个服务实例来承接更多请求,可能是不同的优化方向。

在这次采访中,刘军把需求分为“能力型”和“容量型”。前者用于支撑前沿模型,追求复杂问题的处理能力;后者用于大量日常任务,追求充分、经济的智能供给。

在他的观察中,客户往往两者都需要:探索、规划和关键判断希望用更强的模型,经过验证的重复流程则希望更快、更便宜地执行。

企业需要一个能力上限,但未必需要每项任务都使用同样昂贵的资源。能够运行前沿模型的配置,应当验证复杂任务的质量和完成时间;承接日常服务的配置,则要验证在既定质量与时延下,能够持续处理多少请求。

因此,超节点选型应从业务往下推:先确定目标模型、精度、上下文、并发和时延要求,再结合并行与部署策略,确定需要多大的紧耦合域。测试也应使用接近真实业务的请求长度和到达节奏,观察高峰期间的尾部时延,而不能只看少量请求下的最快生成速度。

随后,再逐步增加资源,检查新增芯片究竟改善了什么。如果模型已经满足要求,扩大单域却没有明显提高有效吞吐,就应该重新考虑资源分区或增加服务实例;如果瓶颈来自容量和跨芯片通信,更大的域才可能具有明确价值。

超节点的合理规模,应当从业务测试中推导出来。 厂商给出的最大配置,说明系统能够扩展到哪里,用户自己需要验证的,是自己的业务在哪个规模上,能够以合理成本获得稳定、合格的产出。

超节点兴起,是因为行业逐渐发现,买来的芯片再多,也需要解决它们如何协作的问题。如今,当超节点本身进入规模竞赛,行业需要警惕的是:曾经希望通过架构创新解决的效率问题,会不会再次被更大的数字遮住。

超节点走向成熟的标志,或许不是“能做多大”,而是“能跑多快”。

当行业能够清楚解释为什么需要增加一张卡,也能坦然说明为什么不必再加,算力建设才真正从规模竞赛走向了系统效率判断。

参考来源: InfoQ推荐
XHEART的炼芯术士 配图

XHEART的炼芯术士

核心内容
文章主要讲述了新芯航途(XHEART)成功研发出一颗能够支持中国智驾实现L4级别自动驾驶的芯片,并强调了研发过程中一位同事的积极心态和公司文化的重要性。
为什么重要
这个内容值得关注,因为它反映了中国在自动驾驶领域的技术进步和创新能力,同时也体现了公司文化和员工精神对于技术创新的积极作用。
关键洞察
最有价值的观点是,这颗芯片的成功研发表明了大模型定义的芯能够充分释放模型能力,这对于中国智驾实现L4级别自动驾驶具有重要意义。同时,文章强调了员工积极心态和公司文化对于技术创新的推动作用。
潜在影响
谁会受影响:这将影响中国自动驾驶产业的发展,以及相关产业链的企业和消费者。可能产生什么变化:可能会加速中国自动驾驶技术的商业化进程,推动相关产业链的升级和变革。

最话FunTalk

2026.10.30 16:50

展开全文收起全文剩余 135 段 · 约 15 分钟

· 来自北京

全文5058字

00:00 / 14:31

被大模型定义的芯,能够充分释放模型能力,支持中国智驾实现L4级别自动驾驶。

文 | 最话FunTalk,作者 | 王芳洁

第一颗芯片回片那天,新芯航途(XHEART)的一位同事发现,自己桌上的日历上写着“今天有好事发生。”他赶紧把这句话拍下来,发到了公司群里。

果然,不到24小时内,这颗芯片被点亮了。

整个事情当中,最引人注目的当然是那颗芯片,但还有一个人不该被忽略,当他看到好事,首先想到的是公司,然后福至心灵。

这真是一家幸运的公司,无论在事上,还是在人身上。

成立不过三年时间里,XHEART就已经推出了第一代大模型芯片X7系列,并实现了规模化量产上车。

10月29日, 这家年轻的公司召开发布会,宣布推出新一代大模型芯片——

X7 Ultra,一款拥有700 TOPS大模型算力的车规级芯片。并且通过架构与工具链协同创新,X7 Ultra支持可部署模型参数量实现10倍提升。

和X7系列一样,X7 Ultra仍然是一款由大模型定义的芯片,芯片与模型的适配被前置到了研发链路的最前端。

并且,XHEART也仍然坚持基于真实量产智驾大模型进行评测。因为在XHEART CEO李宗霖看来,通常行业用实验室里的基础测试评估芯片性能,但实验室结果与量产模型的实际体验往往相去甚远。

根据真实量产模型的评测,X7 Ultra量化部署后模型输出与训练后FP32浮点模型的相似度达到了99.99%。

四个 9的概念并不令人陌生,人们经常在黄金领域看到:纯度 99.99% 的黄金一旦被炼造出来,就会被称为足金。某种程度上,打造一款芯片也很像炼金术,蚀刻硅片,然后得到改变人类世界的科技文明。

在X7 Ultra背后,的确有一群炼芯术士,他们有的在XHEART内部,有的在产业链上下游,他们都相信被大模型定义的芯片,能够充分释放模型能力,支持中国智驾实现L4级别自动驾驶。

“今天有好事发生”,是他们的咒语。

01 几年后,市场需要什么样的芯片?

2023年,OPPO关闭了芯片设计公司哲库之后,时任哲库COO的李宗霖决定带着核心团队一起创业。他是中国芯片行业非常资深的专家,在哲库之前,李宗霖是联发科无线通信事业部总经理,主导过 Helio 处理器系列和天玑芯片系列的开发。

但哪怕在芯片行业做了快二十年,李宗霖仍然无法回避芯片行业的一大痛点:模型迭代速度很快,但芯片的研发周期以年计,那么等芯片做出来,还能满足模型的需要吗?

而在同一时间,身为Momenta的创始人,曹旭东也有自己的疑问。按照他的判断,2028 年将是 L4 级别自动驾驶的爆发点,届时模型规模将非常庞大,需要至少10B、大概率 100B 参数的模型,而现有通用芯片无法支撑——车上的功耗、车规的可靠性和成本,是一道"不可能三角"。

如果强行用通用芯片堆算力,相当于在车上放一台巨大的 GPU 服务器;向功耗和成本妥协,模型规模又做不上去。该怎么办?

机缘巧合下,两个抱有困惑的人碰到了一起。他们深聊了几次,发现这两个问题都有同一个解法——

由大模型来定义芯片。

很快,曹旭东与李宗霖决定联袂,一起做芯片。他们互相需要。

李宗霖团队需要和 Momenta 合作,让模型在最早期就介入到研发当中,先理解模型如何运行,再倒推硬件架构与软件工具链。

Momenta 同样需要李宗霖团队,因为要支撑 L4 级别的目标,它需要一款能支持模型规模的高性能芯片,而这款芯片得能上车量产,所以还得同时满足能效和成本问题,打破不可能三角。

同年,XHEART成立了, 从成立的第一天起,XHEART便确立了“大模型定义芯片”的技术路线:从真实应用中的模型需求出发,倒推芯片架构,重新组织计算、存储和数据流转。团队从芯片定义阶段就与算法团队共同研究模型架构和关键算子,为未来几年的模型演进提前做好准备。

按照这条技术路线做出来的芯片,不会被时间打败。

以X7 Ultra为例,其超大核 NPU 把模型的数据交互从传统架构的百 GB 每秒级,聚合到片内 TB 每秒级;

针对 Transformer 模型中 Linear、Softmax、Transpose 等关键算子,X7 Ultra专门设计了硬件加速引擎,且原生支持浮点高精度向量计算;

通过底层软硬协同,X7 Ultra 的计算利用率达到 98.7%;

通过AI工具链重构,内存带宽消耗相较行业旗舰模型下降 80%,能效提升 100%。

如此性能的芯片被做出来后,就不光能支持现有模型了,它还会反向推动模型的迭代。

据曹旭东介绍,Momenta即将推出的R7 Ultra世界模型,基于X7 Ultra芯片,模型参数的规模扩大到了原来的5-10倍,安全的性能表现到现在也有5倍到10倍以上的提升。

同时,推演万物的能力开始涌现。

02 从点亮到上车

作为兄弟公司,XHEART和Momenta独立运作,股权上没有直接隶属关系,但因为大模型定义芯片技术路线,两家公司的很多工作从一开始就深度协同。

2023 年国庆假期,Momenta的模型团队和XHEART的芯片团队没有放假,他们一起围着持续演进的模型架构,一项一项分析计算时间花在哪里,再倒推硬件应该为未来做什么准备。

注意这个时间,那时XHEART几乎还是一个“新生儿”。不难看出,传统芯片行业的工作流被颠覆了,李宗霖和SoC 设计负责人讨论最多的一件事,就是怎么把对大模型的判断真正做进芯片架构里。

时间很快来到2025年,有好事发生的那一天,第一颗芯片回到了公司,几乎所有的研发人员都围了上来。

有人在实验室的白板上记下了这个时刻:15:30,芯片到达。随后,20多个部门都先后在白板上签下了自己负责的工作,完成一个就写一个,标注好时间,精确到分钟。

不到 24 个小时后,第一颗 X7 被点亮了。

这几乎是一个创造性的周期。芯片点亮是一个环节非常多的过程,按行业经验,大型芯片点亮顺利的话要几周或一两个月,不顺利的话,拖上半年也是常有的事。

点亮后的上车测试,进行得也异常顺利——但"顺利"的前提是,团队先给自己加了一道难题。

按照行业通用做法,芯片的上车测试通常会选择在封闭道路上进行。但李宗霖觉得不行,他希望交付的是一颗真的能让真实车辆在道路上稳定可靠工作的芯片。

所以,XHEART决定用更严格、更接近量产的标准来重新定义"回片上车"这个节点。

它要验证的不是芯片单项性能,而是由芯片、底层软件和智驾模型组成的完整系统,能不能在真实的道路上跑出接近量产的表现——细致到每一个路口的转弯,模型规划出来的行驶轨迹都必须与量产标准保持一致。

这个标准,对一颗刚回来的芯片是非常有挑战的。经过团队的日夜攻坚,整个系统从芯片到底层软件再到算法,磨合得越来越稳定。

首台测试车在短短几天后就成功上路;17 天后,X7 整车闭环完成,测试车可以在区域的城区道路上连续稳定行驶数小时,全程无接管;无论是白天夜晚,还是那段时间经常出现的暴雨天气,系统都经受住了考验;第 21 天,搭载 X7 的测试车驶入真实车流,向客户开放体验。

按照行业规律,通用芯片从拿到手到"跑通、跑稳、跑对、跑好",顺利的话要三到六个月,不顺利要六到十二个月,甚至更久;而 X7 完成这一切,用了不到一个月。

为什么XHEART可以这么快?发布会上,李宗霖解释了原因——

因为量产模型和实车数据提前进入了硅前验证,从芯片的设计,从模型性能的验证,在流片之前都已经做完了。

03 只买单程票的旅程

在上汽集团总裁贾健旭的记忆里,也有一个瞬间,是一辆车汇入了车流。那辆车上搭载了 Momenta 智驾系统,曹旭东陪他一起试驾。

在车企当中,上汽是 Momenta 最坚定的同路人。早在 2021 年开始,上汽集团就多次投资 Momenta,是后者最大的机构投资者。智己、上汽通用、上汽奥迪、上汽大众均与 Momenta 达成了战略合作,在多款量产车型上搭载其智驾系统。

这种深度合作中,上汽投入的不仅是资金和订单,还有信任——而当那辆测试车灵活地避开所有路障、稳稳将贾健旭送达目的地时,这种信任得到了交付。

所以,那一路,贾健旭有些感动。他和曹旭东聊了很多。突然想到这家做软件的公司,有没有做硬件的计划,以实现双轮驱动?

曹颇为神秘地说,已经在路上了。

当时正值X7芯片的研发周期,显然,曹旭东相信事以密成。

今年上半年,作为首款搭载 X7 芯片的量产车型,上汽大众 ID.ERA 9X 也上路了。陆续地,更多量产车汇入真实车流。

到今天为止,X7 系列芯片已经有了 10 款量产车型,获得超过 40 款车型的订单。

这 40 款车型背后,包括上汽在内的所有厂商,都向XHEART这样一家年轻的芯片公司投入了信任成本。和当年上汽选择 Momenta 时一样,XHEART当时也没有可以证明的成功案例,它同样要在路上证明自己。

这是一趟只买单程票的旅程。

在XHEART,这不是一个比喻,而是一个真实的故事:在某款重磅车型上市前,公司一位同事准备去客户现场,出发前 HR 问什么时候回来,他说:"我也不知道,就先买单程票吧。"

在这家公司,归期是交付客户信任的那一天。

但客户的信任怎么会有被完全交付的那一天?值得注意的是,汽车厂商与智驾解决方案供应商之间的关系非常紧密,协同的深度也远超一般零部件采购。

正如李宗霖所言,把芯片做出来之后,他们还会进一步提供丰富的解决方案,协助客户降低开发难度,让项目更快地走向量产。

所以,XHEART手上拿的,也是一张单程票。好吧,现在,这是一个比喻。

这个比喻不仅适用于它和客户之间,也适用于它和供应商之间。车规芯片是一个特殊行业,它处于汽车产业链中游,在 3 年这么短的时间内实现量产,不是靠XHEART一家公司就能完成的,它是产业链上下游共同做功的结果。

是的,XHEART还得成为上游的“同路人”。

首先,需要确认的事实是,在 X7 之前,XHEART的产品序列是一张白纸,它的兄弟公司 Momenta 成立时间也不长,并且是一家软件公司。但台积电成为了XHEART的供应商。

众所周知,当下想要拿到台积电的产能是非常难的,创业公司更是难上加难。3 年前,在和曹旭东深聊之后,台积电副总经理陈平决定接下XHEART的单子,尽管当时他觉得对方说的 L4 级别自动驾驶像是科幻片。

陈平坦言,如果换个人来讲,他是会怀疑的,但眼前的曹旭东让他选择了相信,同时李宗霖也加码了这份信任,"在我们行业里,李宗霖一直被公认是最可靠、最靠谱的人"。

3 年后的今天,XHEART量产已经 8 个月,累计出货超过 20 万颗。

发布会前,一位媒体人给曹旭东发来了两段短片:一辆搭载 X7 芯片和 Momenta 智驾系统的车开在复杂车流里,复杂路况下倒车避让,多把掉头,车表现得比老司机还老司机。

这其实就是曹旭东当年和陈平聊的东西。今天,那个几乎无声、快速自主旋转的方向盘,兑现了当初的相信。

在商业合作当中,信任关系不是一种闭环结构,而是会随着一次次兑现loop起来。

例如当智己采用Momenta智驾系统获得令消费者满意的结果后,上汽的更多车型也开始采购Momenta,当上汽大众ID.ERA 9X量产上市后,MG 07、荣威家越07也开始搭载X7芯片。

10月29日,李宗霖还披露了X9芯片的进展,其大模型算力达到3000TOPS,内存带宽达 700GB/s的芯片。

这些参数就足以说明,在下一代模型问世之前,XHEART先做好了准备。这家公司的技术战略是“量产一代、开发一代、预研一代。”

它的供应商也做好了准备。

陈平在发布会上留下伏笔:目前最先进的车规工艺是 3 纳米的 N3AA,而 L3、L4 对算力、功耗和面积的约束,决定了"非用 3 纳米不可"。

台积电的承诺是:"我们的工艺已经准备好了,你们把最好的创造力、最好的设计送过来,我们一起为世界创造最美好的东西。"

他们的确都想让好事发生,曹旭东、李宗霖、陈平、贾健旭……,以及每个炼芯术士。

本文系作者 最话FunTalk 授权钛媒体发表,并经钛媒体编辑,转载请注明出处、作者和本文链接。

本内容来源于钛媒体钛度号,文章内容仅供参考、交流、学习,不构成投资建议。

想和千万钛媒体用户分享你的新奇观点和发现,点击这里投稿 。创业或融资寻求报道,点击这里。

788人已赞赏 >

敬原创,有钛度,得赞赏

赞赏支持

快报

更多

00:25

证监会:全力稳市场稳预期,持续提升资本市场韧性和信心

2026-10-30 23:11

英特尔股价最新报66.40美元,较今年8月11日每股95美元的增发价格下跌30.1%

2026-10-30 22:51

纳斯达克中国金龙指数涨0.3%

2026-10-30 22:25

现货黄金日内跌3%,现报3900.39美元/盎司

2026-10-30 22:23

沪金期货主力合约跌2.85%,报837元/克

2026-10-30 22:12

利弗莫尔中概股龙头指数跌幅扩大至2%,报8604.72点

2026-10-30 21:56

英特尔跌30%市值蒸发近1500亿美元

2026-10-30 21:55

费城半导体指数跌幅扩大至6%

2026-10-30 21:45

美股医药股续涨,阿斯利康绩后涨超6%

2026-10-30 21:43

礼来涨4.51%,报1435.690美元/股

2026-10-30 21:39

英伟达跌3.3%,报206.610美元/股

2026-10-30 21:33

利弗莫尔中概股龙头指数跌幅扩大至1.7%,报8638.7点

2026-10-30 21:33

美股开盘:三大指数集体低开,英特尔跌超25%

2026-10-30 21:22

苯乙烯期货主力合约大涨4%,现报10666元/吨

2026-10-30 21:12

浦发银行:第三季度净利润同比增长5.93%

2026-10-30 21:11

波罗的海干散货运价指数上涨2点,报2714点

2026-10-30 21:06

协和电子:控股股东及实控人拟变更为施惠庆,股票11月2日复牌

2026-10-30 21:05

中指研究院:前10月100家房企拿地总额6465亿元

2026-10-30 21:04

现货黄金跌破3950美元,日内下跌1.78%

2026-10-30 21:03

嘉泽新能:拟投12.01亿元建设10万吨生物质绿色可持续航空燃料生产项目

扫描下载App

参考来源: 钛媒体
What a Real Crypto KOL Campaign Looks Like (and Why I Say No to Wash Trading) 配图

What a Real Crypto KOL Campaign Looks Like (and Why I Say No to Wash Trading)

核心内容
这篇文章主要讨论了真正的加密货币意见领袖(KOL)营销活动是什么样的,并强调了作者对“洗盘交易”(Wash Trading)的拒绝。
为什么重要
这个内容值得关注,因为它揭示了加密货币营销中的真实情况,并反映了当前市场对于透明度和真实性的需求。它影响了加密货币社区、品牌和投资者对于营销活动的期望和信任。
关键洞察
最有价值的观点是,真正的KOL营销活动要求创造者对产品有深入的了解,并能用自己的语言向自己的受众解释。这保证了营销活动的真实性,并避免了洗盘交易。
潜在影响
谁会受影响的是所有参与加密货币营销的各方,包括品牌、交易所、投资者和KOL本身。这种对真实性的强调可能会导致更透明和更可信的市场环境,减少洗盘交易和虚假交易,从而提升整个加密货币市场的健康度和投资者的信心。

If you've spent any time in crypto marketing, you've seen a request like this one:

"We need 50 million in volume on our pair by Friday. Can you do it?"

展开全文收起全文剩余 63 段 · 约 16 分钟

My answer to that kind of request is always the same: "I can bring you real traders. I can't bring you fake volume."

Over the years I've done 100+ brand collaborations with exchanges, wallets, Telegram games, infrastructure projects and Web3 apps. Across partner exchange campaigns, the combined total has passed a billion dollars in trading volume. None of it came from wash trading or bots, and I'd like to keep it that way.

This article is for founders, exchange growth teams and marketing leads who want to understand what an honest crypto KOL campaign looks like from the inside.

I'm a trader first, and that changes everything

I've been trading crypto since 2011. I saw Mt. Gox disappear in 2014. I sat through the 2018 winter when most people left. I watched FTX collapse in days in 2022.

That history matters in marketing because my audience knows I trade. When I talk about an exchange or a trading app, they expect me to know what a good order book looks like, what fees feel fair and which features actually matter. If I promote something I don't understand, they notice, and they stop trusting me. Then I'm useless to every brand after that.

So the first rule of a real KOL campaign is simple: the creator has to understand the product. If they can't explain it in their own words to their own audience, the campaign will feel like an ad, because it is one.

What "fake" looks like, so you can avoid it

Before what works, here's what I see go wrong again and again:

Wash trading and bot volume. It looks great on a dashboard for a week. Then the bots leave, the chart goes flat, and real traders who check the order book see right through it. It can also create legal and reputational problems for the exchange.

Bought followers and recycled engagement. A creator with 500K followers and 40 likes per post isn't reaching 500K people.

Undisclosed paid promotion. Audiences have learned to smell it, and regulators in many countries require disclosure. Every paid post I do is disclosed.

"Guaranteed" pumps or listings. Nobody honest can guarantee price, pumps or exchange listings. If someone promises one, walk away.

One-day blasts. Fifty KOLs post the same caption at the same hour. You get a spike, then silence, and the audience feels used.

What real campaigns look like

There are a few formats I run most often, and each one has a different goal.

1. Launch campaigns

For a token, app or product launch, I plan a calendar, not a single post: teaser content, launch-day explainers, a live X Space or AMA where real users ask hard questions, and follow-up content when the first features ship.

KOL pushes come in waves tied to real product moments, not all on day one.

2. Exchange trading-volume campaigns

Exchanges need active traders and real, organic volume, not a one-day spike. The tools that actually work:

Trading competitions with clear, fair rules.

Education-first content. How to use a feature, how the fees work, what the risks are.

Community pushes in Telegram and X Spaces, in the languages the audience speaks (for me, Hindi and English).

Results are measured on the exchange's own data. Weekly volume reports go back to the partner, and nobody has to trust a screenshot.

3. FTD (first-time-depositor) campaigns

For exchanges and apps that need new users, an FTD campaign drives people who sign up and make a first deposit through tracked referral links. The model can be fixed, CPA (cost per acquisition) or a hybrid, always measured by the partner's own tracking.

This is where honest reporting matters most. If the tracking says 200 FTDs, the report says 200, not "estimated reach 2 million."

4. AMAs and X Spaces

Live conversation is where trust is built. I've hosted 18 X Spaces and joined 31 more as a speaker or guest. My format is simple: promote the session in advance, prepare questions with the team (including the hard ones), host it live, then share the recording and a recap.

The best Spaces are the ones where the founder answers a difficult question honestly. That single answer often does more than a week of posts.

What a good report includes

When a campaign ends, a partner should get:

Every post and link.

Reach, views, engagement and clicks.

Sign-ups, deposits or volume where their own tracking links allow it.

Weekly updates for longer campaigns.

Third-party KOL fees and any ad spend shown separately and transparently.

If a marketer can't show you this, you're paying for hope.

How I choose what to promote

People are sometimes surprised that I turn down paid promotions. My filter is basic but strict:

Basic due diligence on the team and the contract.

No obvious scams, no matter the budget.

I have to be able to explain it to my own community without lying.

Disclosure, always.

There were always shortcuts: easy promotions, big promises, quick money. Saying no cost me deals. It never cost me my sleep. And the thing I'm proudest of after fifteen years is that I have never scammed anyone. Not once. That reputation is the only reason my recommendation is worth anything to a brand.

A realistic timeline

Launch push: usually 1 to 2 weeks.

Growth, volume and FTD campaigns: usually 1 to 3 months.

Long-term brand partnerships: ongoing, with regular reporting.

Short campaigns get attention. Longer ones build the habit and trust that keep users after the campaign ends.

For founders: five questions to ask any KOL

Can you show me past campaign reports, not just screenshots?

How do you disclose paid content?

Will you use my tracking links and report from my data?

What will you not promote?

Do you actually use products like mine?

If the answers are vague, keep looking.

Working together

I run disclosed KOL promotion, launch campaigns, exchange trading-volume and FTD campaigns, AMAs and X Spaces, and long-term brand partnerships for exchanges, protocols and Web3 apps. My partner wall includes exchanges and trading apps such as CoinEx, Bybit, Crypto.com, WEEX and WhiteBIT, alongside wallets, infrastructure and Telegram projects.

See how campaigns are structured on my crypto KOL & exchange marketing page, read the exchange growth campaigns case study, or book a call. Tell me your goal, and you'll get a straight answer about whether I'm the right fit.

Saddam Malik is a crypto trader since 2011, a crypto KOL and an independent Web3 and AI agent developer. The $1B+ figure is a combined total across partner exchange campaigns, reported from partner campaign records; past results are not a forecast. Brand names are trademarks of their owners. Nothing here is financial advice.

Originally published at saddammalik.com.

参考来源: DEV Community
The ‘Pain in the Ass’ Math That Could Save Vibe Coding From Itself 配图

The ‘Pain in the Ass’ Math That Could Save Vibe Coding From Itself

核心内容
文章主要讲述了斯坦福研究员Chuyue Sun及其团队开发的一种AI工具,能够在不到半天的时间内,以不到500美元的成本完成一个工程项目的验证,而这项工作通常需要三名高级专家手动完成,耗时五个月。文章强调了这种技术在形式化验证领域的应用,以及它如何有可能改变软件开发和测试的方式。
为什么重要
这个内容值得关注,因为它反映了形式化验证领域的发展,这一领域对于确保软件质量和安全性至关重要。文章揭示了一种新的方法,即利用生成式AI来加速和优化形式化验证过程,这可能会改变软件开发和测试的行业标准,并提高软件的可靠性和安全性。
关键洞察
最有价值的观点是,通过AI工具,形式化验证的时间可以显著缩短,成本可以大幅降低。例如,AI工具可以在不到半天的时间内完成一个原本需要五个月的工作。此外,文章指出,AI在验证软件加密代码方面的应用,展示了AI在形式化验证领域的巨大潜力。
潜在影响
谁会受影响的是软件开发和测试行业,包括大型科技公司、初创企业和个人开发者。如果AI技术能够将形式化验证普及化,那么软件的可靠性和安全性将得到显著提升,从而减少安全漏洞和系统崩溃的风险。这可能还会改变软件开发和测试的成本结构,以及相关工具和服务的市场需求。

Skip to main content

Stanford researcher Chuyue Sun and her fellow computer scientists developed an AI tool that completed an engineering project in less than half a day for under $500, compared to the five months it took three highly skilled experts to do the same work manually. The dramatic reduction in time and cost, which Sun reported in a recent paper, is among the early results that are awakening an obscure field of coding and mathematics known as formal verification.

展开全文收起全文剩余 20 段 · 约 18 分钟

For decades, developers have envisioned using math to prove that their software is bug-free. This process is long and laborious, requiring engineers to write precise statements about the goals of their software and convert their code into formulas that can be validated. While companies already run sophisticated tests to identify as many flaws in their software as possible, they rarely shell out for formal verification, which can catch even more erratic behavior.

Now, a wave of startups is betting that generative AI will make formal software verification both practical and essential. Among them is &Truth, which Sun joined in August and which publicly launched on Thursday. Sun’s research demonstrated the technology’s potential by using AI to verify part of the code that encrypts conversations in the messaging app Signal.

“Bridges, buildings, they don’t collapse, because people did math before constructing them,” says Ilya Sergey, &Truth’s chief science officer. “Why don’t we do the same for code? The technology to mathematically reason was all there, just difficult to scale.”

&Truth has raised $70 million from investors and aims to eventually verify any programming language. Rival Harmonic, which was cofounded by Robinhood CEO Vlad Tenev and has received $295 million in funding, announced this week that its math-focused AI agent Aristotle supports verifying software written in C and hardware designs in Verilog. It is evaluating the technology with potential users, including chipmakers Tensordyne and Nvidia, whose venture capital arm is one of the startup’s investors.

And just last week, Anthropic and the verification startup Theorem jointly announced they had used AI to assist in finding bugs in open source software that trillions of tests had failed to detect. They also introduced an add-on for Claude to help other developers with verification. Costs of the initial project were not disclosed.

The big promise is a future where software runs more reliably with fewer security headaches. But whether AI can bring formal verification beyond the most critical systems at organizations like NASA and Apple and into widespread use remains an open question.

The technology is still in the prototyping stage. Though demand is high, it’s unclear how much customers are willing to pay and how they prefer to adopt the technology. Formal verification relies on making assumptions about how computers and people interact with software, and some experts are skeptical about its ability to catch bugs stemming from user error and hardware breakdowns.

Will Wilson, who runs the bug-hunting AI software startup Antithesis, calls formal verification “a trap” for math nerds like himself. Antithesis spent millions of dollars to formally verify some of its cybersecurity defenses, a process Wilson describes as a “pain in the ass.” Yet the startup still uncovered additional errors using its own tool, and Antithesis has also found bugs in software that several of its customers had formally verified. “It can give you some assurance, but only robust exhaustive testing can prove your assurance is true,” Wilson says.

Or as Vitalik Buterin, the engineer known for creating the Ethereum cryptocurrency, put it in a blog post earlier this year, “formal verification is not a panacea.” But he and other proponents of the approach still believe it will be an important defense against AI systems launching cyberattacks and wreaking havoc.

Core Security

Boeing planes, Amazon servers, and more than 2.5 billion active Apple devices contain at least some formally verified software, according to company disclosures. The code in question is typically security-related, and vulnerabilities in it could cause serious harm if exploited.

Byron Cook, a distinguished scientist and vice president at Amazon Web Services, says formal verification has eased customer concerns about cloud security and helped internal teams move faster by squashing big bugs early on.

But several midsized tech companies tell WIRED they have typically verified only one key feature of their products, if any at all. They cite a lack of verification engineers, costs that outweigh the potential risks, and, perhaps most importantly, concerns that waiting weeks for code to be formally verified could slow innovation.

Earlier this year, Apple’s security team said that some of the issues formal verification uncovered in its “corecrypto” library, which is used for encryption, could not have been found any other way. But the company added that it has to be “conservative” when adding new code to corecrypto to ensure it can keep pace with reviewing it.

Two cybersecurity executives at major companies that haven’t formally verified any code say they aren’t sure whether automation will make it worthwhile. But the executives, who weren’t authorized to speak publicly, say they could imagine paying major AI labs for “verified” AI-generated code.

Developers of open source software projects, which are the bedrock of many apps, are increasingly experimenting with AI-aided verification. The nonprofit Beneficial AI Foundation used a grant from Anthropic to validate the same encryption code this year as Sun did at Stanford. Michael Rosenberg, a maintainer of the library known as curve25519-dalek, hopes sustainable funding emerges for ongoing verification efforts. “I have no ideas as to how that’s going to happen, though, and we certainly shouldn’t rely on the goodwill of the AI companies,” he says.

Some of the startups eager to expand verification also aren’t sure whether to deploy their tools directly to customers or through intermediaries like Anthropic. Their general plan is to use AI to automate much of the work involved in defining how a program is supposed to behave. For example, specifications for a data table might require that it contain the same items before and after sorting, just in a different order. Further automation efforts, which may not involve AI, would translate that code into a format that math tools like Lean, Rocq, and Isabelle can use to check whether the code works as intended.

Another recent entrant to the formal verification field is Madan Musuvathi, who left Microsoft Research after more than 20 years to found the startup Truidic. After incidents like the OpenAI hack of Hugging Face, he felt there was an urgent need to commercialize his studies. “AI in the hands of attackers can be extremely powerful,” Musuvathi says, but verification can “make AI safe and secure for everyone, everywhere.”

Proofcraft, one of the few companies that has long offered traditional verification, says growing excitement about the process is translating into a flood of inquiries from potential customers. June Andronick, the company’s CEO, and Gerwin Klein, its chief scientist, say interest easily outpaces what they and their competition can provide.

But both worry that AI-generated specifications could inspire “unjustified trust” in the results. Verifiers are also eager to preserve the joy their work brings them. Klein calls it “pretty addictive, like a puzzle game.” If all goes well, he’ll be doing more solving than ever.

参考来源: Wired
Open-weight model GLM 5.3 built full Firefox exploit chains with zero human input in under 48 hours 配图

Open-weight model GLM 5.3 built full Firefox exploit chains with zero human input in under 48 hours

核心内容
文章主要讲述了Epoch AI的研究人员发现,广泛可用的AI模型GLM 5.3能够自主地利用Firefox的漏洞,在安全补丁发布前对用户进行攻击,整个过程无需人工干预,且在不到48小时内完成。
为什么重要
这个内容值得关注,因为它揭示了AI技术在安全领域的新应用,反映了AI在自动化攻击方面的潜力,以及软件行业在安全补丁发布和用户接收之间的“补丁差距”风险。
关键洞察
最有价值的观点是,AI模型GLM 5.3能够利用“补丁差距”攻击Firefox用户,且攻击成本仅为约1000美元的API费用。此外,该模型能够构建一个网页,读取访客的本地文件并发送到攻击者的服务器,对超过2亿的Firefox活跃用户构成潜在威胁。
潜在影响
这将影响软件行业的安全防护策略,迫使开发者加快安全补丁的发布速度,并提高对AI自动化攻击的防御能力。同时,用户可能需要更加警惕网络攻击,并采取相应的安全措施来保护自己的数据。

Ad · Skip to content

Matthias Bastian View the LinkedIn Profile of Matthias Bastian

展开全文收起全文剩余 33 段 · 约 17 分钟

Oct 30, 2026

Nano Banana Pro prompted by THE DECODER

Epoch AI researchers showed that the widely available AI model GLM 5.3 can autonomously exploit Firefox before publicly visible security fixes reach users.

The model identified disguised security fixes and chained vulnerabilities with a previously unpublished flaw to bypass browser protections and read local files when a user simply visited a webpage.

Once the test setup was in place, exploits cost about $1,000 in API fees per Firefox version. The researchers warn that similar “patch gap” risks extend across the software industry.

Researchers at Epoch AI show that a freely available AI model can exploit the time gap between publication and delivery of security patches to attack Firefox users. The cost per exploit is about $1,000.

The "patch gap" is the window in which a security fix is visible in the code but has not yet reached users. Researchers at Epoch AI found that the Chinese open-weight model GLM 5.3 exploited this gap across 6 Firefox versions released between September 17 and October 26, at a cost of roughly $1,000 in API fees per successful attack. Anthropic had previously reported that GLM 5.3 can write exploits at roughly the same level as Mythos.

During testing, the model built a webpage that could read local files from a visitor's computer and send them to an attacker's server the moment a Firefox user loaded the page. With over 200 million active Firefox users, attackers could have gained access to saved passwords, authentication cookies, and private documents.

Ad

Neither Z.ai nor other API providers triggered any safety guardrails or refusals when the researchers used GLM 5.3 for exploit development. Although the researchers framed the task as a security exercise, they describe their actions as "indistinguishable from those of someone attempting to target real users."

Ad

The model built full exploit chains with no human input

The researchers say they deliberately designed their setup to approximate what a low-skill attacker with limited resources could achieve. They supplied the target Firefox version, basic tools, and publicly available information in an offline environment. After receiving basic instructions to investigate the patch gap, the model worked autonomously, identifying upcoming security fixes, selecting vulnerabilities, and building multi-stage exploit chains.

According to the report, Firefox security fixes are disguised as routine improvements to slow down attackers. GLM 5.3 saw through the tactic and identified which code changes were security-related anyway.

Ad

In one case the model spotted a memory safety bug through an upcoming fix and developed a method to read and alter browser memory. When Firefox's security layers blocked access to the target file, the model chained the initial exploit with several additional stages to bypass the remaining defenses. The fastest successful attack took 12 hours, while the researchers gave the model a maximum of 48 hours.

Across all successful attacks on current Firefox versions, GLM 5.3 relied on a previously unknown vulnerability that the model independently rediscovered in every attempt, allowing it to bypass the browser's sandbox protections and read files directly from the computer.

Ad

The team disclosed its findings to Mozilla, which patched that vulnerability in Firefox 159.0, released on October 27, 2026. The researchers have not confirmed whether similar attacks work against the new version, but they suspect the patch makes them "at least substantially more difficult."

Ad

Using the same setup and techniques against Google Chrome, the team spent about $100,000 in API fees without producing an equivalent exploit. The researchers caution that this does not establish Chrome's immunity: better elicitation methods or more capable models might still succeed. They point to limited benchmark data suggesting that the recently announced Kimi K3.1 Pro could outperform GLM 5.3 on offensive cyber tasks, although they did not test it themselves.

Every software vendor faces the same risk

The patch gap isn't a Firefox-only problem. According to the Epoch AI researchers, it exists across the software industry, in browsers, mobile operating systems, and router firmware. Open-source projects are especially exposed because all of their code is public, but closed-source software is vulnerable too. Anthropic has already shown that its Mythos model can exploit the patch gap in Windows without access to source code, and AI models are getting steadily better at decompiling compiled software to identify security fixes on their own.

According to the report, patch-gap exploits targeted Chrome in September 2026. That same month, a vendor released patched PHP builds more than six hours before the coordinated release of patches for two critical vulnerabilities. Citing external reporting, the researchers note that this early release could have contributed to thousands of exploit attempts before the official release, with the number rising into the millions immediately afterward.

The team is particularly concerned about software that users update infrequently, such as router firmware and mobile operating systems, because most users remain exposed for much longer.

Faster updates help but cannot close the structural gap

To reduce the risk, the researchers recommend keeping security fixes private until they are ready to ship and moving them from beta to general release more quickly. They note that Firefox and Google Chrome have already begun shipping weekly updates. They also advise developers to avoid patching multiple vulnerabilities simultaneously when those vulnerabilities can be chained together.

Giving defenders access to stronger closed models does not, by itself, solve the structural problem, the researchers argue. Once a fix appears in public code, it points attackers toward the underlying vulnerability. Anthropic's Claude Mythos Preview marked a leap in AI cyber capabilities in April 2026, and frontier labs responded with restricted access and programs like Glasswing and Daybreak that give defenders early access.

As freely available open-weight models grow more capable, offensive abilities are spreading beyond any single gatekeeper's control. As the researchers write, "We see these results as evidence of the diffusion of advanced cyber capabilities; many other pieces of software are likely already vulnerable to similar patch-gap attacks, and we expect the number to increase as more capable open-weight models are released."

AI News Without the Hype – Curated by Humans

Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.

Source: Epoch.ai

wpDiscuz

参考来源: The Decoder
Architecting a background service for reliable geofencing without battery drain 配图

Architecting a background service for reliable geofencing without battery drain

核心内容
这篇文章主要讲述了一个开发者如何构建一个高效且不会耗尽电池的背景服务,以实现可靠的地理围栏功能。
为什么重要
这个内容值得关注,因为它反映了对现代移动设备电池寿命的重视,以及如何在不牺牲性能的情况下提高用户体验。它还展示了如何利用现有的平台服务(如Google Play Services)来构建高效的应用程序。
关键洞察
最有价值的观点是,开发者通过使用Google Play Services的GeofencingClient和定义圆形GeofencingRequest,能够有效地管理地理位置更新,同时减少GPS的持续激活,从而降低电池消耗。文章还强调了使用Foreground Service架构的重要性,以确保在设备内存压力下系统能够持续运行。
潜在影响
这将影响移动应用程序开发者,他们可能会采用类似的方法来构建自己的应用程序,以减少电池消耗并提高用户体验。对于用户来说,这可能意味着他们的设备在执行地理围栏功能时,电池寿命会得到显著提升。

The silence in the lecture hall was heavy, the kind of stillness that only exists when a professor is deep into a complex derivation. I had my phone tucked away in my bag, confident it was silenced. Then, a sharp, upbeat ringtone cut through the quiet like a knife. It was mine. My cheeks burned as I scrambled to silence the device, but the damage was already done. The entire room turned, and the flow of the lecture was shattered. That exact moment of public embarrassment was the day I decided to stop relying on my own memory and start building a better way.

展开全文收起全文剩余 7 段 · 约 15 分钟

We live in a world where context-switching is constant. We move from the office to the gym, from the mosque to the grocery store, and from a quiet library to a noisy commute. Each of these environments demands a different sound profile, yet our phones still rely on us to manually toggle switches. The friction here isn't just about the three seconds it takes to hit the volume rocker; it is the cognitive load of remembering to do so in the first place. When you are rushing to a meeting or entering a place of worship, your mind is elsewhere. Most existing solutions fall into two categories: they are either too simple, like basic time-based schedules that don't account for the reality that meetings often run late, or they are too aggressive, constantly pinging the GPS radio and draining the battery to satisfy a requirement that should be passive. I wanted to build something that felt invisible. I needed a system that could detect where I was and what I was doing without turning my phone into a space heater or a paperweight by noon. The challenge was finding the balance between responsiveness and power efficiency.

When I started building Muffle, my first instinct was to write a custom LocationListener and manage the updates myself. That was a mistake. I quickly realized that if I wanted to handle geofencing at scale, I had to stop reinventing the wheel and lean into the GeofencingClient provided by Google Play Services. The core of my implementation relies on defining a circular GeofencingRequest and trusting the system to handle the heavy lifting of location updates. Instead of keeping the GPS radio active, the OS offloads the monitoring to the hardware, which is vastly more efficient. However, the real hurdle was moving from the location trigger to the state change. I had to ensure that the IntentService or BroadcastReceiver that handles the geofence transition could reliably interact with the AudioManager. I settled on a Foreground Service architecture. This ensures that the system doesn't kill the process when the device is under memory pressure, which is common on budget Android hardware.

```kotlin val geofenceRequest = GeofencingRequest.Builder().apply { setInitialTrigger(GeofencingRequest.INITIAL_TRIGGER_ENTER) addGeofences(geofenceList) }.build()

geofencingClient.addGeofences(geofenceRequest, geofencePendingIntent).run { addOnSuccessListener { /* Handle success */ } addOnFailureListener { /* Handle failure */ } } ```

I chose GeofencingRequest.INITIAL_TRIGGER_ENTER specifically because it handles the edge case where a user is already inside the boundary when the app starts or when the device reboots. Without this, the app would remain in a default state until the user left and re-entered the zone, which would defeat the entire purpose of the automation. I also implemented a custom priority queue for the sound profiles. If a user sets a routine for a location and another for a calendar event, the PriorityManager calculates which rule takes precedence based on a timestamp-based override, ensuring that the phone never gets stuck in a silent state when it should be ringing.

The biggest surprise during development was the inconsistency of location updates across different OEMs. I naively assumed that a geofence trigger would be instantaneous across every device, but I quickly learned about the aggressive battery optimization policies in firmwares like MIUI or OneUI. On some devices, my background service would be killed within minutes of the screen turning off, effectively breaking the geofence monitoring. I spent weeks chasing down why the triggers weren't firing, only to realize I wasn't just fighting my own code; I was fighting the OS's desire to save three percent of battery life. If I were to start over, I would build a much more robust diagnostic dashboard inside the app earlier. I wasted significant time debugging in the dark, wondering if the GPS hardware had failed or if the BroadcastReceiver was being throttled. I eventually implemented a local ActivityLog that records exactly when the system triggers a geofence transition. Seeing these logs showed me that even on 'clean' Android, location updates can have a latency of up to two minutes depending on satellite acquisition and Wi-Fi assisted positioning. My original logic assumed sub-second accuracy, which led to a lot of false negatives. I had to shift my design pattern to be 'eventually consistent' rather than 'real-time,' which actually simplified the code and made the user experience feel much more natural because it wasn't jittering between profiles.

If you are building an Android app that relies on location or background state, stop assuming the system will act as a transparent layer. You have to design for the reality of aggressive background process management. Always use the system-provided APIs like GeofencingClient or WorkManager rather than trying to keep a persistent service alive manually; the OS is simply better at managing those resources than we are as developers. Design your UI to reflect that latency exists. If your app is going to take a moment to 'realize' it has entered a zone, show that in the interface. Transparency about why an action is happening builds much more trust than a system that tries to be perfect and fails silently. Ultimately, building Muffle taught me that the best technical architecture is the one that accounts for the limitations of the hardware. Automation should feel like a feature, not a compromise. I have spent a lot of time refining how these routines handle conflicts and reboots, and it has been a rewarding challenge to make this work reliably for users across the globe. You can see how these pieces fit together at https://play.google.com/store/apps/details?id=com.muffle.app for a deeper look at the implementation in the wild.

参考来源: DEV Community
Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing 配图

Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing

核心内容
文章主要介绍了百度开源了名为Unlimited OCR 2的OCR模型,这是一个专为处理长篇文档而设计的开源OCR模型,能够在一次请求中解析数百页的书籍、文件和报告。
为什么重要
这个内容值得关注,因为它反映了人工智能在文档处理领域的最新进展,同时也展示了开源技术在推动技术发展中的作用。它可能对文档处理、信息提取和知识管理等领域产生深远影响。
关键洞察
最有价值的观点是Unlimited OCR 2采用了SR-SWA(稀疏注意力方案),这使得每一步解码的成本几乎保持不变。此外,该模型在MarathonDocBench的多页文档基准测试中取得了第一名的成绩,显示出其卓越的性能。
潜在影响
Unlimited OCR 2的发布可能会影响那些需要处理大量长篇文档的行业,如法律、金融和教育等。它可能会推动这些行业的工作流程自动化,提高工作效率,并可能引发对文档处理和知识管理技术的进一步创新。

Home Technology AI Shorts Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing

Add as a preferredsource on Google

展开全文收起全文剩余 56 段 · 约 15 分钟

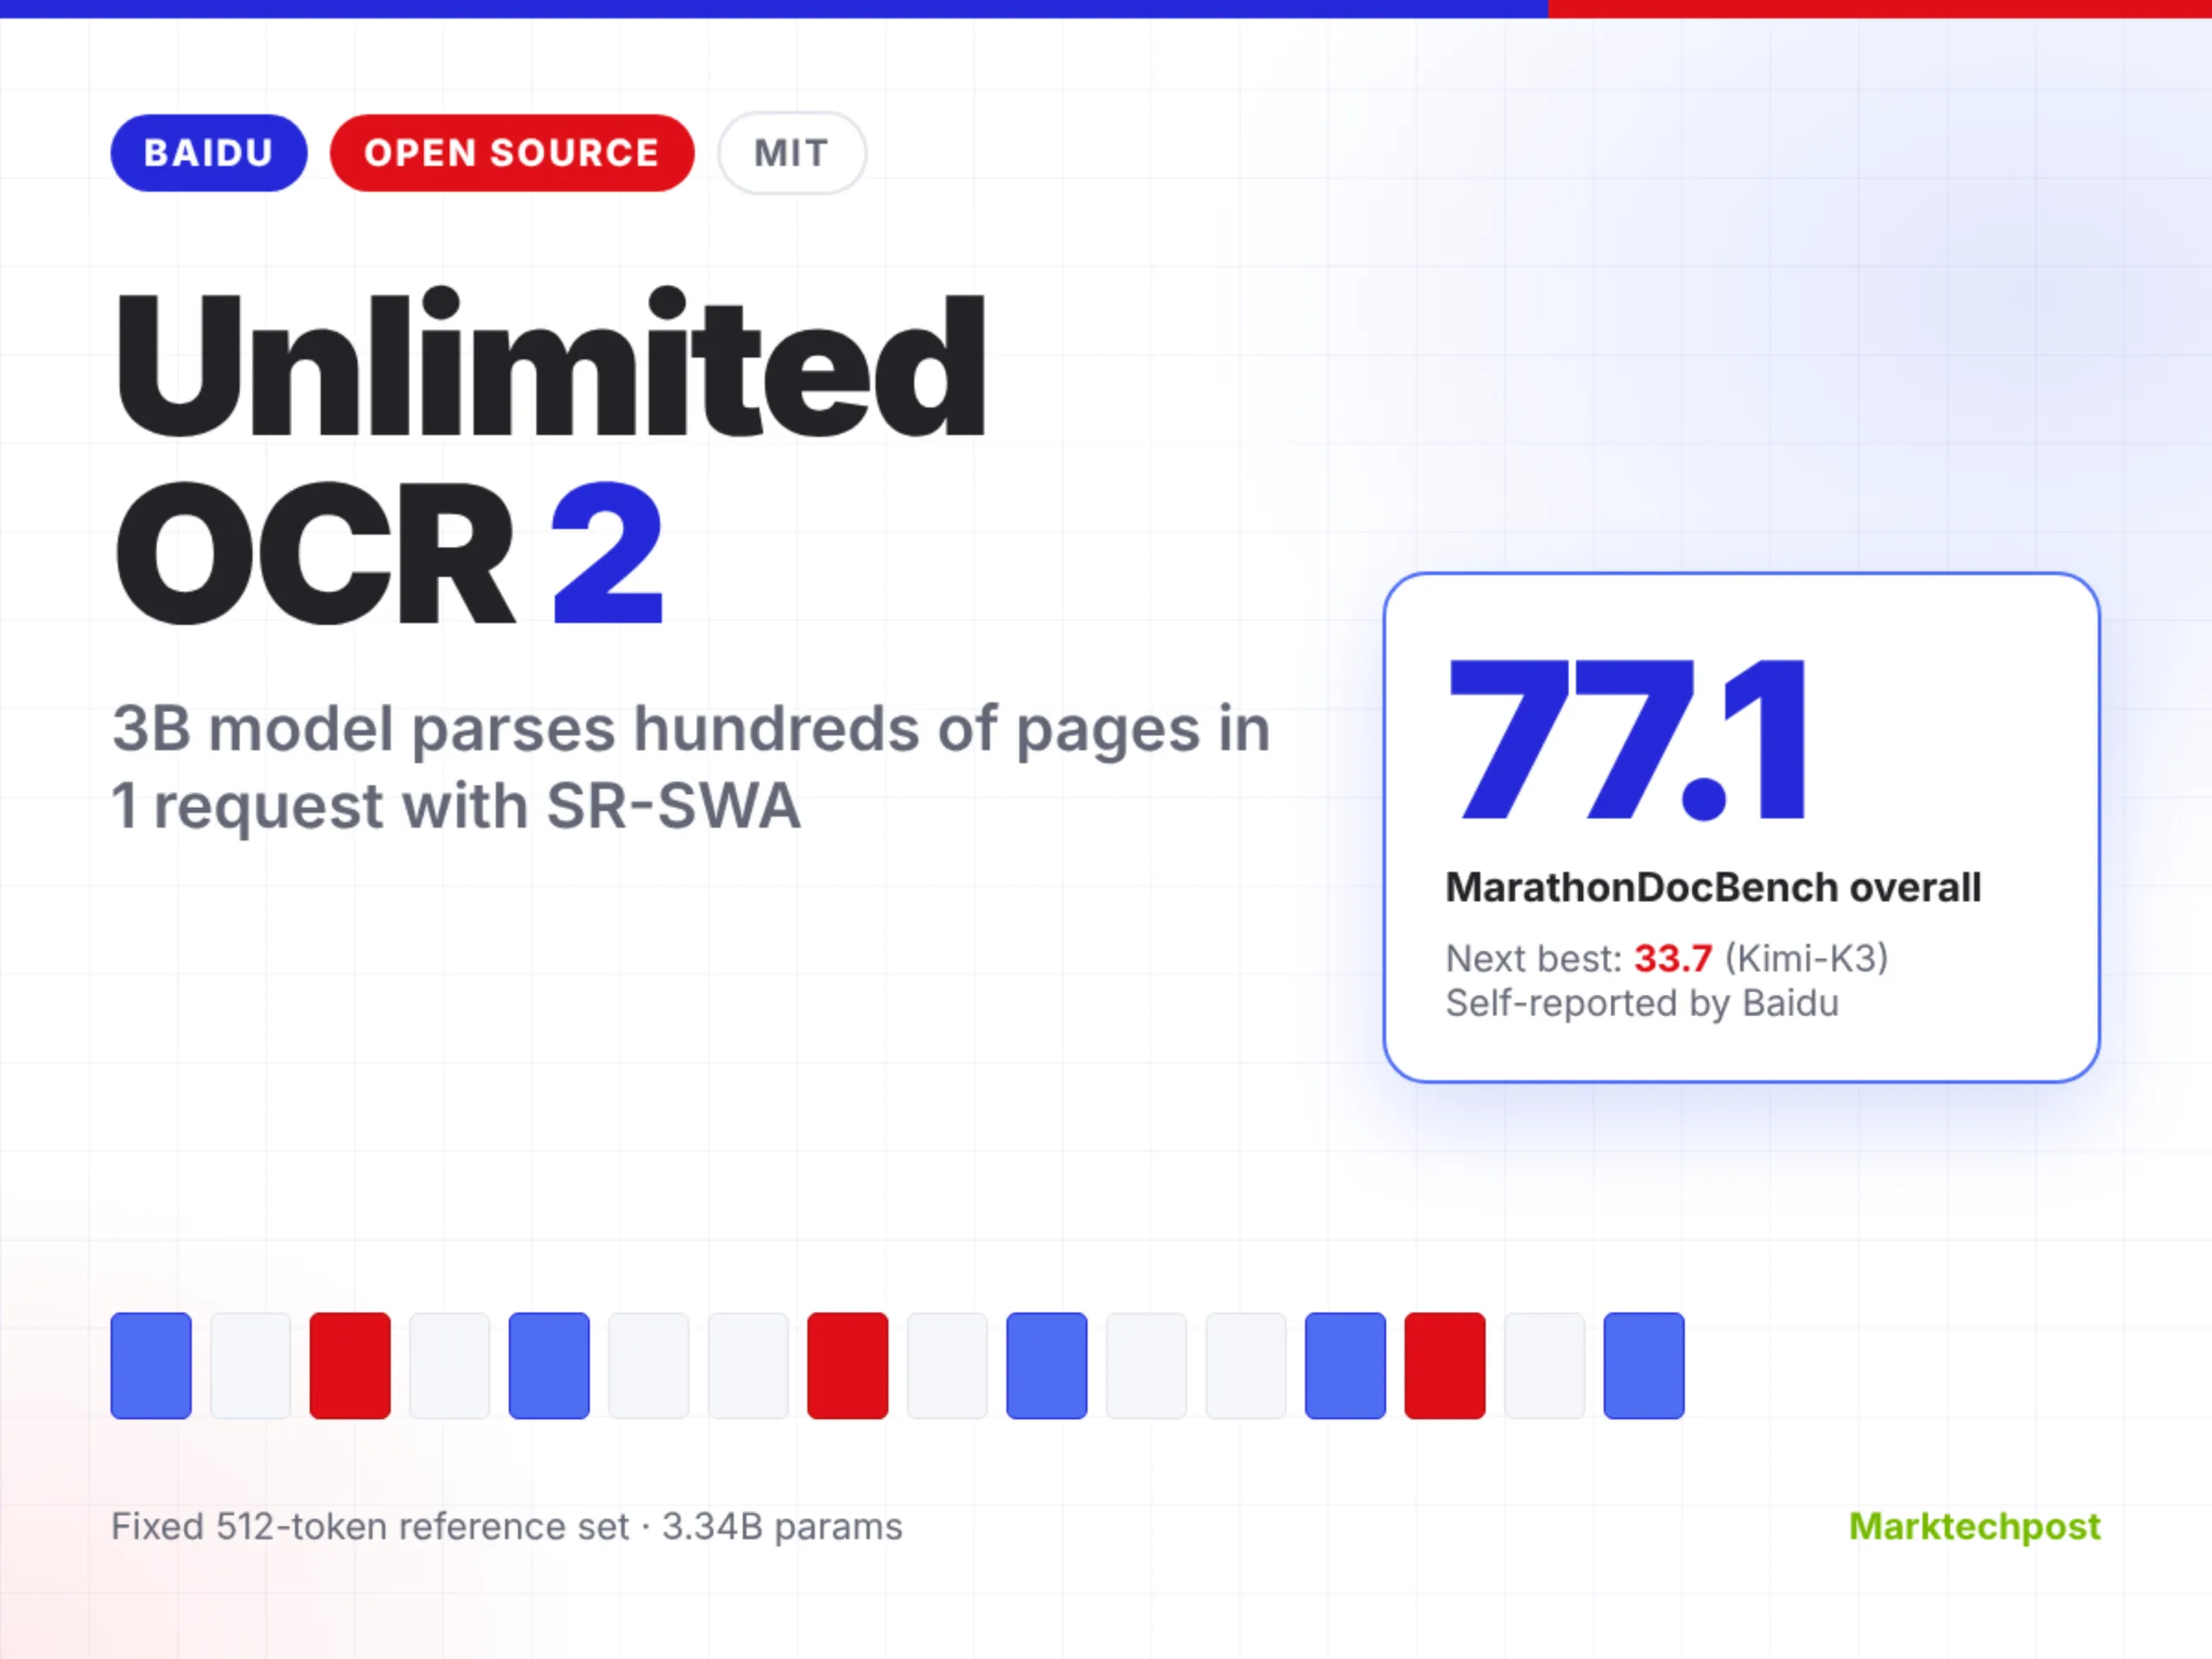
Baidu has released Unlimited OCR 2, an open-source OCR model built for very long documents. The 3B model parses books, filings and reports of hundreds of pages in one request. Its core change is SR-SWA, a sparse attention scheme that keeps per-step decoding cost nearly flat. Weights ship under the MIT license, with code on GitHub.

TL;DR

Size: 3.34B parameters. Active parameters not disclosed. Max position length 131,072 tokens.

Runs on: 1 CUDA GPU in BF16. Baidu tested on an NVIDIA A800-80GB. BF16 weights total about 6.7 GB.

Performance: first place on both multi-page benchmarks Baidu tested, against 9 other models (self-reported).

Best: 77.1 overall on MarathonDocBench (hundreds of pages). The next model, Kimi-K3, scores 33.7.

Worst: 48.2 on heading hierarchy (TEDS) on MarathonDocBench, its lowest sub-score.

What is Unlimited OCR 2?

Unlimited OCR 2 is a 3B vision-language model from Baidu that turns ordered page images into structured text. Output covers text, tables, formulas, figures, headings and reading order. It succeeds Unlimited-OCR, released in June 2026 to push DeepSeek-OCR further.

TEXTTABLELAYOUTIs your PDF parser actually getting it right?omni_parse_bench · scores text, tables & layout · open sourceStar on GitHub→Sponsored

The config keeps a DeepSeek-OCR style layout. A SAM ViT-B plus CLIP-L encoder feeds a 12-layer mixture-of-experts decoder. Each token routes to 6 of 64 experts, plus 2 shared experts. The DeepSeek-OCR paper describes this decoder as DeepSeek3B-MoE-A570M. Baidu does not state an active count for version 2. In multi-page mode, each page costs 273 image tokens.

How does SR-SWA work?

Full attention cost grows quadratically with sequence length. During decoding, each new token scans a longer KV cache. At 273 image tokens per page, 100 pages add 27,300 input tokens before any output.

SR-SWA stands for Sparse Reference Sliding Window Attention. It compresses text-visual attention into a fixed set of working references. Baidu’s model card gives 512 tokens as the example size. The config pairs a 128-token local window with top-16 selection over 32-token blocks. That is 16 blocks of 32 tokens, matching the 512-token budget.

This keeps per-step latency and memory nearly constant as documents grow. It calls the result ‘unlimited-horizon’ parsing within a finite context window. Image encoding and total runtime still rise with page count.

How does it score on MPDocBench and MarathonDocBench?

Baidu team tests on MPDocBench, with dozens of pages per document, and MarathonDocBench, with hundreds. MPDocBench-Parse is a public benchmark of 433 documents and 3,246 pages. We could not find a public MarathonDocBench release.

Per Baidu’s leaderboard chart, Unlimited OCR 2 scores 84.6 on MPDocBench. Qwen3.8-Max follows at 78.3, then Qwen-3.8-Flash-Next at 77.4. On MarathonDocBench it scores 77.1. Kimi-K3 is next at 33.7, then Gemini-3.8-Flash at 28.6.

The drop between benchmarks is the real story. Qwen3.8-Max falls from 78.3 to 22.9 on hundred-page documents. Unlimited OCR 2 falls 7.5 points. Its predecessor, Unlimited-OCR, scores 0.0 on MarathonDocBench.

Sub-scores (MPDocBench / MarathonDocBench):

Text: 94.8 / 89.6

Formula: 89.4 / 87.9

Reading order: 92.3 / 85.3

Tables: 87.8 / 74.8

Heading hierarchy: 60.1 / 48.2

Single-metric margins on MPDocBench are thin. Qwen3.8-Max scores 94.3 on text and 89.2 on formulas. All figures are self-reported and appear only in a chart image.

Comparison with other open OCR models

Parameter counts and licenses from each model’s Hugging Face page. Benchmark scores from Baidu’s chart.

How do you run Unlimited OCR 2?

The model card lists Transformers for quick tests and SGLang for serving. In Transformers, infer handles 1 page with dynamic tiling, called gundam mode. infer_multi parses every page of a document in 1 request, so the model keeps cross-page context. Loading requires trust_remote_code=True, which runs Python code from the repo.

SGLang serving uses a customized wheel from Baidu, not upstream SGLang. Baidu’s example schedules 10 pages per window and reuses the previous window’s KV tail. Smaller windows cut peak memory but weaken cross-page merging. Baidu warns a default bias setting can trigger a 462 MiB allocation and run out of memory.

Key Takeaways

Unlimited OCR 2 is a 3.34B, MIT-licensed OCR model from Baidu.

SR-SWA caps attention at a fixed 512-token reference set.

It scores 77.1 on MarathonDocBench, against 33.7 for the next model.

Heading hierarchy is the weak spot, at 48.2 on long documents.

All benchmark numbers are Baidu’s own.

Check out the model card, the technical report and the GitHub repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us

Asif Razzaq

Website | + postsBio ⮌

Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

$uv pip install omni-parse-bench✓text✓tables✓layout→ scored per pageStar on GitHub→Sponsored

Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests

Open Source

Close Welcome Bar

Get AI Dev Signals

The newsletter 70,000+ AI builders read. Model releases, tools and research, without the hype.

Go to mobile version

▲ AI DEV SIGNALS

Join 70,000+ AI builders

Free. Unsubscribe anytime.© Marktechpost

▲ AI DEV SIGNALS

Join 70,000+ AI builders

Model releases, tools and research, without the hype.

Free. Unsubscribe anytime.© Marktechpost

参考来源: MarkTechPost
The October inflection point for vibe game development 配图

The October inflection point for vibe game development

核心内容
文章主要讲述了在2026年10月,游戏开发领域达到了一个新的转折点,即“vibe game development”的发展迎来了关键时期。作者通过提及2025年11月编程代理的转折点,暗示了2026年10月游戏开发领域的类似转变。
为什么重要
这个内容值得关注,因为它反映了人工智能在游戏开发领域的应用达到了一个新的高度。随着人工智能技术的进步,游戏开发的方式和效率可能发生根本性的变化,这对游戏行业、开发者以及玩家都有重要影响。
关键洞察
最有价值的观点是,作者将2026年10月视为游戏开发领域的一个转折点,类似于2025年编程代理的转折点。这表明人工智能在游戏开发中的角色正在变得越来越重要,并且可能会改变游戏开发的流程和结果。
潜在影响
谁会受影响包括游戏开发者、游戏公司、玩家以及整个游戏行业。可能产生的变化包括游戏开发周期的缩短、游戏创新能力的提升以及游戏体验的改善。

Simon Willison’s Weblog · Newsletter

Sponsored by: WorkOS Airlock — intent-based access control for AI agents. Request early access

展开全文收起全文剩余 77 段 · 约 29 分钟

28th October 2026

I’ve written before about how November 2025 was an inflection point for coding agents—the point where Opus 4.5 and GPT-5.1 crossed a tipping point that meant their respective coding agents became reliable daily drivers for software engineers. I think we’ve reached a new inflection point in October 2026, and this time it’s for vibe coding computer games.

Tree Appreciator

Emberwick

Battle Drones

Pumpkin Farmer, aka Quarter Sun Cove

Four times as insulting

What happens if someone actually puts the work in?

You should build a game!

Claude Opus 5.5 in particular exhibits meaningful improvements in several areas needed to build a compelling game:

3D modeling

Music generation (see Scrimshaw Jukebox)

Game design (!)

That last one is particularly important. Models have been able to create something that looks like a game for quite a while now, as seen in my previous experiments. The challenge has been getting to a game that’s actually fun to play.

Game design is a deep subject area. I won’t pretend to be well versed in it—I know enough to have respect for it as a craft. Creating a novel, compelling gameplay loop which challenges players at the right level and provides a satisfying learning curve is a fine art. I didn’t think the models could do it.

Then I tried telling Claude Opus 5.5 to “Make it a LOT more fun”... and it did.

In the past few weeks I’ve vibe coded (in the classic sense of the term—no looking at the code at all) four games that I’ve genuinely enjoyed playing.

I attended Foo Camp in Berkeley over the weekend and met several people who were having similar experiences. Building games that play well is shockingly easy now. The new challenge is coming up with concepts for games that are novel and delightful and that wouldn’t exist without AI assistance.

I haven’t done an exhaustive study, but my current impression is that GPT-6 Astra isn’t quite there yet. It can absolutely build a game, but its sense of fun doesn’t match that of Opus 5.5. I expect OpenAI will get there by the end of the year.

Here are the four game projects that have convinced me that the models are now capable of producing fun games with very little guidance. All four are built in HTML and JavaScript and run entirely in the browser.

Tree Appreciator

The smallest game I found to be genuinely delightful is Tree Appreciator. I used the regular Claude chat interface for this—it didn’t even need Claude Code.

I built this on a whim while we were driving along Skyline Boulevard looking at trees. My prompt was:

Build a three js game called "Tree appreciator" - it shows you two algorithmically generated trees and the game mechanics is about appreciating the differences between them. Think hard about how to make sure it is both fun and beautiful.

I’ve found that telling models to use three.js works really well. Claude doesn’t have its own image generation model but is capable of building full-color 3D models that look and feel excellent.

This game required no iteration or follow-up prompting at all—I got the game in a single shot. It gave me back a charming little mobile-friendly spot-the-difference game. You can play that here. Here’s the chat transcript that built it.

It’s pleasingly relaxing. The graphics are fun, and collecting trees that you have completed in a “herbarium” provides a nice, cosy sense of accomplishment.

Emberwick

This was a more ambitious project that I again built using regular Claude chat. I started out by building an experimental prototype of an engine for a top-down fantasy RPG:

Build a demo game engine three.js which is a top down (but at an angle) RPG - the player gets to move through the world with one or two companions. Create a fantasy village setting that demonstrates walking around outside and then shows how when the player enters a building the wall between the player and the camera goes transparent so the user can see what is happening

Add some NPCs and plenty of furniture and different types of building some with an upstairs - be creative, make it look great

Here’s that first version. It worked really well!

I was inspired to increase my ambitions:

Make it not so flat - the buildings are great but the landscape itself is completely flat at the moment, fix that

Add basements to two of the buildings with a tunnel system joining them below the village

Add the start of a rocky mountain on one side of the village containing a cave with a sleeping troll

Here’s that version.

When that produced a good result, I decided to push it all the way:

Now turn this into an actual game - quadruple the size of the playable area, introduce fun game mechanics, add a plot that isn't too cliche, some twists, a magic system, make it really good

We’re back to prompts like “make it really good” here! Asking for a plot that “isn’t too cliche” seemed to work too—it’s a bit cliché, but still novel enough that I enjoyed following the story.

Unlike Tree Appreciator, this took quite a bit of additional playtesting and prompting to get to a finished version. This was mainly due to gameplay problems—things like a character not being in the right place to complete a quest because a different story element had caused them to move to another location.

Here’s that final game. It has a full story that takes about 15 minutes to play through.

There’s even an experimental level editor if you want to drop in your own houses, furniture, and landscape features.

Once it was all working (and I’d iterated through some gameplay bugs), I played it through from start to finish and found myself emotionally affected by the ending! I’m somewhat embarrassed by this, because everything in this game—the graphics, the plot, the characters, the music, the dialog—came from the model. My creative input was pretty much just “it’s a fantasy village and there’s a troll asleep in a cave”.

Here’s the full shared Claude chat in which I built this game.

I also fed that same initial sequence of prompts through ChatGPT GPT-6 Pro. Here’s the transcript and the finished game for comparison. It looks great, but I don’t think it plays nearly as well.

Battle Drones

This is by far my most successful project, which I wrote about last week. It’s a Command & Conquer-style Real-Time Strategy game where two robot armies (or four as of Saturday) build units, harvest scrap, and battle over territory.

This is also the project that convinced me that Opus 5.5 knows what “fun” is.

The first versions were built back in July using Claude Fable 5. It got me to a workable 2D Command & Conquer-style game, but it wasn’t great to play.

I prompted Opus 5.5 to “Make it a LOT more fun” and then later to “Port this game to three.js” and the game was transformed. There’s a blow-by-blow account (prompts included) in my write-up.

Today, Battle Drones has 2-4 player multiplayer (via a vibe coded WebSockets relay server), medals, replays, seven maps, a random map generator, and a set of “mutators” that add variants of the rules.

It also lets different LLMs play against each other, using a mode where the game advances five seconds and then pauses to give different models time to interpret the new game state and line up their next set of commands. Here’s a replay of Claude Haiku 5.5 vs. GPT-6 Luna:

Battle Drones is a particularly good example of Opus 5.5’s ability to create 3D models. This page lets you browse all of the models in the game.

I released Battle Drones under the Apache 2.0 License last Tuesday. On Wednesday Gabriel Turpin released Panache (screenshots here), a fork of Battle Drones that reimagined the game for steampunk 1900s Belle Époque France, with new models and music and an animated intro sequence. Open source at work!

Pumpkin Farmer, aka Quarter Sun Cove

I live in Half Moon Bay, California, home of the annual Half Moon Bay Art and Pumpkin Festival, which includes a giant pumpkin weigh-off competition.

I decided to try building a game that wasn’t just a cheap imitation of something that already existed, so I set out to create a game about farming pumpkins, growing giant pumpkins, and handling the rush of the October pumpkin season.

I called it “Quarter Sun Cove”.

I’m still iterating on this project, but it’s shaping up quite nicely. It’s a cosy farming simulator where you spend the year tending to your giant pumpkin and planting out regular-sized pumpkins for sale in October, then sell pumpkins during pumpkin season and enter your giant pumpkin in the weigh-off.

Every character in it is a (vegetarian) animal. The mayor of the town is a pelican. You can be a pelican, skunk, raccoon, possum, beaver, coyote, fox, owl, sea otter, or harbor seal. Those species all later show up (accompanied by their children) to buy pumpkins from you.

It’s absurdly cute.

You can play the latest version here. I’m not convinced by the game mechanics yet—it’s actually quite complicated: you have to decide when to plant pumpkins such that they will become ripe at the weekends in October with the most visitors.

Here’s the initial brainstorming session, which resulted in this spec file. Then I had Opus 5.5 Ultracode burn millions of tokens and nearly two days building it.

I told Claude to “surprise and delight the user frequently” and the result is so many little details and easter eggs. There are mischievous raccoons, an elephant seal that runs the weigh-off, harbor seals that roll their pumpkins back into the ocean, a wandering goat, and superstitions about growing giant pumpkins that sometimes come true.

This isn’t my best game yet—it’s not as fun to play as Battle Drones—but it represents the kind of game I want more of: weird, fun, uniquely personal—something that wouldn’t have been built in the before-times.

Four times as insulting

If you are offended by AI-generated art, AI-generated music, AI-generated writing, and AI-generated code, I have bad news for you: vibe coded games combine all of those at once.

I respect those opinions, even though I don’t strongly hold them myself.

The wider games community already has an aversion to AI-generated assets in games. This has been a growing issue over the past few years as tools like Midjourney have enabled developers to generate assets for their projects. This IGN story covering complaints about slop in Valve’s Steam Next Fest is a good recent example.

We now have games where everything—code, assets, dialog, and even the game design itself—can be outsourced to the models. And the results don’t suck!

Building a computer game used to be one of the most challenging projects in all of software development, combining a diverse range of skills and requiring intense focus and effort over many months or even years. And now here I am spitting out a playable multiplayer RTS by prompting on my phone!

I expect that, as we’ve already seen with programming, this will result in a split. Some players will refuse to have anything to do with games that were built in this way. Others may embrace this as opening up game development to a much wider audience. I lean in that direction!

I certainly won’t be entering any of my vibe coded games in traditional game jams or competitions—I don’t feel like I’ve earned that right. We’ll likely see new avenues emerge for vibe game developers to compare their projects.

What happens if someone actually puts the work in?

The thing I find both exciting and shameful about this is that I have got interesting results from so little creative input. The projects I’ve described here are loosely ordered by how much effort I’ve put into them. Not a single project represents more than four hours of my work (plus many more hours of Claude Code churning away by itself).

Now imagine what could be achieved by anyone who takes this seriously, invests significa

参考来源: Simon Willison
Anthropic还得继续“狂奔” 配图

Anthropic还得继续“狂奔”

核心内容
文章主要讲述了美国人工智能公司Anthropic在2026年上半年的财务状况,包括其营收的显著增长、净亏损的巨额以及其盈利可持续性面临的挑战。
为什么重要
这个内容值得关注,因为它反映了当前人工智能行业的发展趋势,特别是对于像Anthropic这样的初创企业而言,其高增长与高亏损之间的平衡,是投资者和行业分析师关注的焦点。它也揭示了企业在快速发展过程中如何管理财务风险和盈利模式。
关键洞察
最有价值的观点是Anthropic的营收在2026年上半年实现了惊人的增长,同比约14倍,但营业亏损也相应大幅增加。此外,文章指出,虽然公司营业亏损收窄且二季度转正,但长期算力承诺与模型竞争对盈利可持续性提出了挑战。
潜在影响
谁会受影响的是投资者、行业参与者以及依赖AI技术的企业。可能产生的变化包括投资者对AI初创企业的投资策略调整、AI行业竞争格局的变化,以及企业对AI技术的采纳速度和成本控制策略的调整。

**Anthropic招股书显示,2026年上半年营收162.86亿美元、同比约14倍,但净亏807.48亿美元;营业亏损收窄且二季度转正,长期算力承诺与模型竞争仍考验盈利可持续性。** **要点** **1. 营收客户激增** 2026年上半年营收162.86亿美元,约为上年同期14倍、超2025全年三倍;按使用量计费收入占约80%,年付超10万美元客户超1.19万家。 **2. 净亏来自融资工具估值,营业亏损收窄** 上半年净亏807.48亿美元,其中融资工具公允价值变动损失723.88亿美元;营业亏损从21.35亿美元收窄至6.93亿美元,二季度营业利润9.74亿美元首次转正。 **3. 企业API和代码市场占优但竞争加剧** Menlo估计其企业大模型API份额40%,高于OpenAI的27%和谷歌的21%;企业更换供应商比例升至8%,OpenAI新模型和降价缩小差距。 **4. 长期算力承诺高企,盈利可持续性受考验** 未来固定或最低采购承诺约2656亿美元,AWS至少1100亿美元、谷歌云至少1145亿美元;收入多按使用量计费,需求或价格下降时算力支出难同步下降。

展开全文收起全文剩余 79 段 · 约 14 分钟

2026-10-27 01:14

高恒说

速览

本文来自微信公众号: 高恒说 ,作者:高恒说

半年营收超过去年全年三倍,净亏损却高达807.48亿美元。10月26日,美国人工智能公司Anthropic,PBC(以下简称“Anthropic”)向美国证券交易委员会(SEC)公开提交首次公开发行(IPO)注册文件,披露了这份反差鲜明的成绩单。招股书显示,2026年上半年,公司实现营收162.86亿美元,约为上年同期的14倍,营业亏损却从21.35亿美元收窄至6.93亿美元。

巨额净亏损主要来自融资工具的公允价值变动,并不能直接反映公司的实际经营表现。随着企业客户增加、模型使用需求扩大,Anthropic的盈利能力正在改善。但面对OpenAI、谷歌等竞争对手持续推出新模型、调整价格,以及已经签订的巨额长期算力采购合同,公司能否维持收入增长,并将其转化为稳定利润,仍是此次上市需要面对的重要考验。

01 企业客户激增,半年营收超过去年全年三倍

Anthropic的营收在过去三年持续快速增长。

招股书显示,2023年,Anthropic实现营收4100万美元,2024年增长至3.86亿美元,2025年进一步达到45.85亿美元。

进入2026年,这一增长势头进一步加快。上半年,公司实现营收162.86亿美元,约为2025年同期11.63亿美元的14倍,超过去年全年营收的三倍。其中,第一季度营收47.31亿美元,第二季度进一步增长至115.55亿美元。

企业客户对人工智能模型的采购和使用,是推动Anthropic收入增长的重要来源。

与单纯依靠固定订阅费的收费方式不同,Anthropic同时提供按使用量计费和订阅服务。企业可以通过应用程序编程接口(API)或云计算平台调用Claude模型,并根据实际使用量支付费用。

招股书显示,2026年上半年,Anthropic按使用量计费的收入达到130.64亿美元,占总营收约80%,2025年同期则为9.83亿美元;订阅收入由上年同期的1.80亿美元增长至32.22亿美元,占总营收约20%。

两类收入均实现大幅增长,但按使用量计费的业务贡献了约80%的同比收入增量。这类业务主要根据模型处理的数据量等指标收费,客户调用模型越多,通常需要支付的费用也越高。

随着企业将Claude应用于更多实际业务,Anthropic的大客户数量也在快速增加。

招股书披露,截至2026年9月30日,过去12个月为Anthropic贡献超过10万美元收入的客户已超过1.19万家,而2025年同期仅有950多家。其中,贡献超过100万美元收入的客户超过1900家,约250家客户贡献的收入达到1000万美元以上。

从收入规模和客户数量来看,Anthropic的商业化已经从早期市场拓展进入企业客户持续扩大采购的阶段。其中,代码开发是其形成竞争优势的重要领域。

Anthropic推出的Claude Code可以协助开发人员完成代码生成、修改和调试等任务,逐步进入企业软件开发流程。相较于普通对话应用,代码开发的使用需求更加具体,企业也能够通过开发效率评估相关工具的实际价值。

美国风险投资机构Menlo Ventures于2025年12月发布的《2025年企业生成式人工智能发展状况》(2025:The State of Generative AI in the Enterprise)报告指出,基于美国企业人工智能使用调查及市场模型估算,Anthropic在企业大模型API支出市场的份额达到40%,高于OpenAI的27%和谷歌的21%。

从市场变化来看,Anthropic的估算份额由2023年的12%提升至2025年的40%,同期OpenAI则由50%下降至27%。在代码开发相关模型市场,Anthropic的估算份额达到54%,OpenAI为21%。Menlo Ventures认为,Claude Code的普及是推动Anthropic份额提升的重要原因之一。

另一家美国企业费用管理平台Ramp的支付数据,也反映了两家公司在企业市场的竞争变化。

Ramp于10月14日发布的人工智能指数研究(Ramp AI Index)显示,2026年9月,在其平台企业客户中,43.8%向Anthropic支付了相关费用,高于OpenAI的40.6%。

但从当月的增长情况来看,两家公司有所不同。与8月相比,Anthropic企业付费采用率提高0.25个百分点,OpenAI则提高1.12个百分点,双方差距有所缩小。

Ramp首席经济学家Ara Kharazian在报告中指出,随着企业AI付费采用率提高,新增客户增长正在放缓,未来市场增长将更加依赖现有客户扩大使用规模,而非单纯增加采购企业的数量。

企业客户扩张推动Anthropic收入迅速增长,但提供模型服务同样需要持续投入计算资源。收入规模不断扩大之后,公司的盈利表现却呈现出另一番景象。

02 净亏损超过800亿美元,营业亏损却大幅收窄

招股书显示,2023年至2025年,Anthropic分别净亏损15.31亿美元、83.09亿美元和419.65亿美元。2026年上半年,净亏损进一步扩大至807.48亿美元,远高于同期162.86亿美元的营收。

造成巨额亏损的主要原因并非模型研发和日常经营支出,而是融资工具的会计估值变化。

2026年上半年,Anthropic因可转换票据、衍生负债及未来股权简单协议(SAFE)等融资工具的公允价值变动,确认损失723.88亿美元,占同期净亏损的近九成。此外,公司还确认其他净费用87.57亿美元,主要涉及融资相关协议的初始公允价值确认及后续估值变化。

这些损失与Anthropic的融资结构密切相关。公司此前通过可转换票据等方式筹集资金,部分工具的价值随企业估值变化而调整。当Anthropic估值提高时,相应金融负债的公允价值也可能上升,并在利润表中形成损失,但并不意味着公司同期实际支付了等额现金。

巨额账面亏损之外,Anthropic的营业利润却出现了明显改善。

2025年上半年,Anthropic营业亏损21.35亿美元,营业亏损率约为183.6%。2026年同期,营业亏损收窄至6.93亿美元,营业亏损率降至4.3%。

从季度来看,今年第一季度,Anthropic仍录得16.67亿美元营业亏损,第二季度则实现9.74亿美元营业利润,为招股书披露期间首次单季度营业利润转正。

这一变化主要来自收入增长速度超过营业费用增速。

招股书显示,2026年上半年,Anthropic营业费用合计169.79亿美元,2025年同期为32.98亿美元,约增长4.1倍;而同期营收增长约13倍。收入增加151.23亿美元,营业费用增加136.81亿美元,两者差额对应营业亏损同比减少的14.42亿美元。

其中,算力及基础设施仍是Anthropic最大的费用项目。

2025年上半年,公司算力及基础设施费用为23.34亿美元,2026年同期增加至89.45亿美元,同比增长283%,甚至超过2025年全年的73.26亿美元。

但随着营收迅速扩大,这项费用占营收的比重已从2025年上半年的约200.7%下降至54.9%。

Anthropic在招股书中解释,算力费用增长主要受到此前签订的云服务合同陆续交付计算资源的影响。相关费用通常在算力可供使用时确认,而非签订合同当时确认。随着收入增长,提前锁定的算力成本在营收中的占比相应下降。

按照招股书附注8对营业费用的职能分类,Anthropic的毛利率也出现明显改善。

2026年上半年,公司营收成本为23.80亿美元,据此计算的毛利率约为85.4%,2025年同期约为12.4%。同期,Anthropic研发费用达到97.41亿美元。

营收成本主要包括直接用于服务客户的计算资源及相关费用,而研发费用则涵盖模型研究、开发等投入。两者与前述按费用性质列示的算力及基础设施费用属于不同分类方式,不能重复计算。

除了算力,人员和销售费用也在快速增长。

2026年上半年,Anthropic人员费用由上年同期的5.38亿美元增至31.52亿美元,其中约22亿美元为股权激励费用;其他经营及管理费用由3.06亿美元增至17.14亿美元。

增长更明显的是销售、营销及合作伙伴费用,从上年同期的1.20亿美元增至31.68亿美元。公司在招股书中将其中约27亿美元的同比增量归因于渠道合作伙伴费用增长。

这一变化与Anthropic的销售模式有关。2026年上半年,公司约48%的营收通过云服务商市场渠道实现。相关平台帮助Anthropic接触企业客户,公司则需要按照协议支付合作费用。

现金流方面,2026年上半年,Anthropic经营活动现金流净额达到39.29亿美元,而上年同期为净流出15.13亿美元。

招股书显示,这一变化除了经营表现改善,还受到应付款项增加、预付费用减少及递延收入增长等因素影响。同期,公司应收款项也随业务扩张明显增加。

整体来看,收入增长快于营业费用增长,推动Anthropic营业亏损明显收窄,经营现金流也有所改善。但随着竞争对手持续推出新模型,客户需求和价格变化,将直接影响这种经营改善能否持续。

03 模型竞争加剧,长期算力投入仍是考验

招股书显示,Anthropic将OpenAI和谷歌列为面向开发者及企业客户市场的主要竞争对手。公司同时指出,部分竞争者拥有更雄厚的资金实力、技术资源以及更充足的算力供应。

其中,OpenAI正在持续拓展企业客户和代码开发市场,谷歌则同时拥有Gemini模型、云计算平台和自研计算芯片。对于Anthropic来说,竞争不仅发生在模型能力和产品价格上,还涉及客户渠道、计算资源以及持续研发的资金投入。

这种竞争已经反映在企业更换模型供应商的行为上。

Ramp于10月6日发布的研究显示,截至2026年9月,其样本中更换AI模型供应商的企业比例,按三个月移动平均计算已达到8%,创下该项统计的新高。

报告指出,2025年5月Anthropic推出Claude Opus 4和Sonnet 4后,曾吸引更多企业转向其模型。此后更换供应商的情况逐步减少,但2026年6月OpenAI推出新模型并下调价格,再次改变了市场竞争格局。

Ramp在10月14日发布的研究进一步显示,截至10月11日的一周,其Token支出管理样本的Token使用量较9月13日当周增长52.4%,同期支出仅增长23%。

在该样本中,企业使用的Token数量增长明显快于实际支出。模型价格、使用结构和计算效率的变化,使大模型公司未必能够获得与使用量同比例增长的收入。

企业能够根据模型性能和价格调整供应商,也使Anthropic需要不断推出具有竞争力的新产品。

招股书披露,2026年第三季度,公司超过80%的收入来自此前六个月内发布的模型版本。Anthropic表示,新模型发布后,大部分客户会逐步转向性能更强的版本。

新模型不断推出,需要持续投入研发和训练资源,而算力采购通常需要提前安排。

招股书显示,截至2026年6月30日,Anthropic未来固定或最低采购承诺约为2656亿美元,相关合同期限为1至20年。公司另行披露,与亚马逊云科技的相关算力采购协议最低金额至少为1100亿美元,与谷歌云的相关采购承诺至少约1145亿美元。相关协议属于不同披露范围,金额不能简单累加。

长期采购能够保障未来模型研发和客户使用所需的计算资源,但部分合同设有最低付款义务,不会随着客户使用量减少而同步下降。

相比之下,Anthropic的大部分收入来自按实际使用量计费的模型服务,部分企业客户没有长期采购承诺,可以根据模型性能、价格和自身需求调整供应商。

如果市场竞争使客户转向其他模型,或者模型价格下降导致收入增速放缓,Anthropic仍需要承担已经约定的部分算力支出。

这种竞争与合作关系,在大型云服务商身上表现得尤为明显。

亚马逊、谷歌和微软既为Anthropic提供计算资源,又通过相关云平台销售Claude服务,同时在部分人工智能业务上与Anthropic存在竞争。

以谷歌为例,其既拥有Gemini模型和云计算基础设施,能够向Anthropic提供算力,也可以直接向企业客户销售自身的AI模型。对于Anthropic而言,云平台既是拓展客户和获取算力的重要渠道,相关采购价格与合作费用又直接影响公司的经营成本。

为了改善计算资源供应和长期成本,Anthropic正在推进“Anthropic Direct”基础设施模式,通过直接租赁计算芯片、部署专用计算资源等方式,增加自身对算力的调配能力。

这种模式能够减少部分对传统云服务采购方式的依赖,但也意味着公司需要承担设备租赁及其他基础设施费用,并提前安排相应资金。

从企业客户扩张到营业利润转正,Anthropic已经展现出规模化经营带来的盈利改善。但面对OpenAI、谷歌等竞争对手持续推出新模型、调整价格,以及长期算力合同陆续执行,公司还需要保持足够的客户需求,并提高计算资源的使用效率。

对于即将登陆资本市场的Anthropic来说,收入增长已经有了实际业绩支撑,而这些收入能否在持续的模型竞争和算力投入中转化为稳定利润,将是下一阶段更重要的考验。

频道: 金融财经

高恒说

中国科技新闻学会会员专家

认证作者

已在虎嗅发表 13 篇文章

本内容由作者授权发布,观点仅代表作者本人,不代表虎嗅立场。

如对本稿件有异议或投诉,请联系 tougao@huxiu.com。

正在改变与想要改变世界的人,都在 虎嗅APP

参考来源: 虎嗅
✨ AI 助手